Blog

  • The Wrong Way to Build It Passed — Found by a Different Pair of Eyes

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 9)


    On the evening of September 14, 2026, the fixed utf8conv passed its acceptance criteria.

    Acceptance criteria are the conditions for saying “it is done,” written out in a form that can be counted. This time there were 18 of them. The fixed code was run and checked against them, and not one failed. When I write “judgment” in this article, I do not mean detecting character encodings; I mean judging whether the criteria were passed.

    But before that pass, a hole had already been found — on the side that does the judging.

    The judging side assumed only one way of handling the screen. When the screen is handled some other way, it misses it. In fact, even a deliberately inappropriate implementation passed every acceptance criterion that existed at the time.

    Last time was the story of how I wrote “it works.” This time is the story of that hole, which sat just before “it passed.”

    First, Let Me Set Out Who Does What

    Last time, I wrote that I leave both the development record and the article drafts to AI, and that I publish after reading through and correcting them myself. Here, let me explain that division of roles a little.

    When I was developing this in March 2026, I was going back and forth between two AI tools.

    One is Claude Code, a tool that runs inside the terminal (the screen where you type commands as text) and has AI write code. I had been using its name since the first installment of this series without ever saying what it was.

    The other is Claude.ai, the chat version of Claude.

    I consulted Claude.ai on how to proceed in general, and had it produce ideas on how to move forward and the actual instructions for implementation. I handed those instructions to Claude Code, had it do the implementation, and had it report the result. I passed the report to Claude.ai, which checked the contents and made a judgment. Sometimes it produced an instruction sheet for corrections; sometimes it gave an OK and we moved on to the next step.

    The “separate the core from the GUI” story from the second installment of this series also came up this way — as an idea for the right way to implement things, while I was actually alternating between the two tools.

    Time passed, and by September the way the work ran had changed. The work now revolves around a document called a brief. A brief is a document, written before the work is handed to the builder, that says what to build and what to check to count as a pass.

    • The role that writes the brief. It writes the brief and checks what comes back. The AI in this role does not write code that goes into the product.
    • The role that builds to the brief. It receives the brief and writes code or articles. The Claude Code in this role is what fixed utf8conv’s code.
    • The role that reads with a different pair of eyes. An AI other than the one that made them reads the brief and the judging mechanism, and looks for holes.

    Every role is held by an AI. The one who decides what to adopt is me.

    What Judged the Pass Was a Mock Part

    The acceptance criteria were not something a person checks by looking at the screen; they were in a form a machine runs automatically. What ran them was the working machine used by the AI in the role that writes the brief. The mechanism, too, was built by the AI in the role that writes the brief.

    That machine did not have tkinter (the part that puts up the screen, which I wrote about in the third installment of this series), so a mock part was made: something that only imitates tkinter’s behavior and receives commands. Nothing appears on any screen. It is a made-up thing that merely records which command wrote what.

    In utf8conv, as I wrote last time, the job of drawing the screen and the job of converting files proceed at the same time, in separate flows. The main flow is in charge of the screen; the conversion flow is in charge of converting. Inside the program, the conversion flow is called the worker.

    As I wrote in the third installment, the program was built by the practice that the main flow is the only flow allowed to touch the screen’s parts with its own hands. When the conversion flow wants to put something on the screen, there are three ways it can do so.

    • Write it by its own hand. The conversion flow bypasses the main flow and writes text into the log area, or changes the look of a button, itself. By command name, this means insert and config. It is the worst way, and the brief forbids it as worse than asking with a message.
    • Ask with a message. The conversion flow does not touch the screen’s parts itself; it leaves a message for the main flow: “Later, please display this.” The main flow puts it up when it has a free moment. The self.after(0, ...) that I described in the third installment as the way of asking “please display this” is this one. “after” is the name of the command for leaving such a message. This is the way my March self used, believing it to be safe.
    • Stack it up. The conversion flow only stacks what it wants displayed into a box, and the main flow comes by a little at a time, picks it up, and displays it. This is the correct answer, and the current rule.

    The mock part had been given just one rule.

    “An after() called from the worker thread simply vanishes; nothing happens.”

    As I wrote last time, at midday on September 14, only the heading lines came out on my screen. The mock part’s rule is a direct copy of what the screen looked like at midday. That the messages were being silently discarded, without even raising an exception (notice of an error), was confirmed by the small test I wrote about last time — after the mock part had been made.

    What Happens When There Is Only One Rule

    The mock part discards displays that are asked for with a message. So when the criteria were run against the code before the fix, the displays did not arrive, and it failed, as it should have.

    In the code before the fix, the command that leaves a message was written in 5 places. The newest version of the judging tool finds these 5 places and fails them.

    But commands that write by their own hand were a different matter: the mock part accepted them as they were. The written text stays in the mock part, and the look of the button changes too. Seen from the judgment’s side, the display arrived properly, and the button came back.

    In other words, if you run the criteria against an implementation in which the conversion flow writes to the screen by its own hand, without using messages, the judgment misses it. A way of building it that can behave even less stably than the code before the fix ends up passing.

    It was the role that writes the brief that made the mock part. That role had not noticed this hole.

    Found by a Different Pair of Eyes

    What found the hole was the AI in the role that reads with a different pair of eyes.

    At this point, the role that writes the brief was running two reading AIs, separately. What it showed them was the brief and the judging mechanism. The instruction was “Find reasons not to approve.” The viewpoints were split, and one of the two was given the job of attacking the judging mechanism itself.

    That one wrote deliberately badly built code of its own, as a sample for testing the check itself. It was not meant to go into the body of utf8conv. It was an implementation in which the conversion flow does not use messages and writes to the screen by its own hand. When the criteria were run against it, every criterion that existed at the time went through.

    After the Hole Was Closed, It Passed

    The role that writes the brief added one more rule to the mock part.

    The added rule was: “If the screen is touched from the conversion flow, record it.” Whether it was asked with a message or written by its own hand, if a record remains, it fails.

    This addition, too, turned out to have an omission. The next readers — two AIs reading with a different pair of eyes — both found that dialogs, such as the small window that reports an error, were missing from the record. The role that writes the brief closed that as well.

    After the criteria had been fixed, the role that builds to the brief fixed utf8conv’s code. This is the fix I wrote about last time: from asking, to picking up what has been stacked. The role that writes the brief did not take the report “It passed” at face value; it ran the criteria once more itself to check. The result was a pass on all 18.

    Let me write the order down once more. The hole is found. The recording rule is added to the mock part, and the hole is closed. Only after that does the fixed code pass all of the criteria.

    The code that passed in the end did not slip through the hole. It passed under the judgment made after the hole was closed.

    Counting the Times

    Because the recording rule was added, it also became possible to count how many times the screen had been touched from the conversion flow. What is counted is not the number of places where the command is written (5 places), but the number of times it was called.

    Counted by the judgment, the code before the fix, over the course of running every one of the judgment’s scenes, left 3,590 messages for the screen from the conversion flow. Everything counted was a message. The number of times it wrote by its own hand was 0.

    The code after the fix stopped both the messages and the direct writes; it only stacks things up. Counted the same way, the number of times the screen was touched is 0.

    It Became a Rule on September 14

    The practice of not touching the screen’s parts by hand from the conversion flow had, as I wrote in the third installment, been there since March. utf8conv’s current rule is written as that practice with one thing added.

    Do not touch tkinter from the worker thread. after() counts as touching, too.

    It was written in this form on September 14, 2026. What was added is the part that says asking with a message also counts as touching.

    My March self used that way of asking. In the third installment, I described it as a safe practice. In March, the rule that counts even messages did not yet exist. Something that later became a rule, I believed at the time to be safe.

    A Pass Was No Substitute for My Own Hands

    Even after the pass, the role that writes the brief wrote in the judgment record something to the effect of: “Even so, there is no skipping the owner of this product running it with his own hands.” The reason is that the mock part is a made-up thing that only records the commands it receives; it is not the real screen.

    That evening, I ran it from the screen with my own hands. The scene I wrote about at the end of last time — the first time the files in the folder I had prepared for checking were converted from the screen — came after this whole series of exchanges, and after the pass on the acceptance criteria had been confirmed.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.
  • I Wrote That It Works — Yet I Had Never Converted a File from the Screen

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 8)


    At the end of the last article, I lined up the milestones from “it works” to “it can be distributed” in four lines. “It works” is the first of them.
    At least at the time the original article was written, around March, my understanding was that this program “works (on my own computer).”
    In reality, I had never once tested running a conversion from the screen (the GUI),
    but at the point when I wrote “it works” in March, I was treating it as done, including the part where the screen is connected.
    The “never once” in this article refers to the period from that March until midday on September 14, 2026.

    Inside the single word “works,” there were several separate things, and the ones that held and the ones that did not had been rounded off into that one word. This time is the story of untangling what was inside.

    The Three Scenes Inside “It Works”

    First, let me set out the three scenes, in order.

    March 2026: I Ran a Dry Run

    The first scene is March 2026. As I wrote in the third installment of this series, the one where I completed the MVP, I ran utf8conv against my own folder. The way I ran it was a Dry Run.

    The target was 51 files, and all 51 were judged to be UTF-8, judged to be files with no need for conversion. Since it was a Dry Run, nothing was written to the files, and the number of files converted was zero.

    (The conversion itself, from around this time, I had been running inside the tests. Not a human operating it with a mouse, but a form where it is left to the test tooling and run automatically. A state of not going through the screen, in other words.)

    Late Night on September 5: The Tests and the Conversion Passed

    The second scene is half a year later, late at night on September 5, 2026.

    Last time, I wrote that I had run an inspection of the state of the product candidates; this is from when the inspection of utf8conv was done. This inspection was something AI ran automatically while I was asleep.

    Of the inspection, the tests and the conversion passed. The tests: 426 collected, 354 passed. The remaining 72 are skips. The character encoding conversion, too, actually went through.

    However, the screen was not opened, and the result of the inspection said the following.

    ★ Passed by calling the core functions directly, not the GUI. Via the GUI is unconfirmed.

    The GUI is that screen, the one with the windows and buttons. core is the part behind that screen that actually determines the character encoding and converts it. What AI did was an inspection that said, “Without going through the screen, I called the part behind it directly and confirmed that the conversion goes through.”

    Because the tests can be run automatically, the practice was to start the tests when going to bed and check after waking up. For this reason, there was never any occasion to look at the screen in the first place.

    Midday on September 14: Only the Heading Lines Came Out

    The third scene is midday on September 14, 2026.

    On my own computer, I opened the utf8conv screen and pressed the run button. The way I ran it was a Dry Run.

    Only the first few lines, the lines that serve as the heading of the run log, came out, and after that not a single line appeared. The run button stayed gray, in a state where it could not be pressed, and did not come back, and the progress bar did not move either.

    At this point, the state was, “I cannot really tell whether it is running or not. Has it hung up??”

    Lining Them Up

    When the three scenes are lined up, the contents of “it works” come to this.

    • March 2026: I ran a Dry Run. All 51 files were UTF-8, and the number of files converted was zero
    • Late night on September 5: the conversion passed. The screen was not opened
    • Midday on September 14: I ran it from the screen. Only the heading lines came out, and nothing after that. It also looked as if it had hung up.

    None of them is something you could not call “it works.” But a scene where a file was converted from the screen and succeeded — that is, a situation confirming that file conversion is achieved along the entire path a user goes through when using this program — there was not one among these.

    The Same Line Dropped Out Every Time Things Were Summarized

    Then where did the first milestone line, “it works (on my own computer),” come from?
    Following the records, inside the inspection record files, the one line “the screen is unconfirmed” had dropped out twice.

    The first is the inspection result file.

    In the body of the result file, it was properly written.
    In the field for checking startup: “GUI unconfirmed (an environment with no screen).”
    In the field where conversion was tried: “Via the GUI is unconfirmed.”
    In the list of things that could not be confirmed: “Starting the GUI and converting via the GUI (because the environment has no screen).”

    Yet at the very top of the same file, in the field where the conclusion is written in one line, it says this.

    Partially works. The tests and the main features passed completely, but there is not a single procedure in the repository for building a distributable.

    While the strong expression “passed completely” is there, not a word about the GUI is included. Within the same file, only the one summarizing line had dropped it.

    The second is the summary of the whole inspection.

    This is the inspection result files for each development project, folded into a single document in order to confirm where the projects stand as a whole. Here too, the preface says that for products with a screen, startup and the main features cannot in principle be confirmed. In the utf8conv row of the overview table, too, “⬜ GUI unconfirmed” remains.

    Yet in the field that lines up a one-line comment per product, there is a line that begins like this.

    UC/utf8conv ★ The contents are good (426 tests passed, and the main features passed too), but (the rest omitted)

    Here too, the GUI has dropped out. What is more, what had been three numbers side by side in the result file — 426, 354 passed, 72 skipped — had become “426 tests passed.”

    Put the two side by side, and the way they dropped it is the same. Where things are written in detail, it is properly there every time, but the moment things are summarized briefly, everything other than the conspicuous achievements drops out, every time. In two separate documents, both times, it dropped out in the same way.

    One of the causes of this kind of phenomenon lies partly in the way these blog articles are written. I have AI record the development log, then have AI shape an article based on its contents, and then I read it through, scrutinize it, and correct it — that is the practice.

    It was AI that ran the inspection and wrote the result file, and AI that wrote the summary. Presumably, I would guess, this was because when AI referred to the materials, it referred only to the briefly summarized parts and did not check as far as the body.

    Still, the one who read the draft produced by that practice and let the line “it works (on my own computer)” through as it was, was me.

    September 14: What Did Not Reach the Screen

    Back to the story of midday on September 14.

    Inside utf8conv, the job of drawing the screen and the job of converting files proceed at the same time, in separate flows (threads of work that proceed side by side within the program). In the third installment of this series, I had written about that mechanism like this.

    The conversion flow doesn’t touch the screen directly; instead, using the form self.after(0, ...), it asks the main flow, “Please display this.” The side that was asked carries it out when it has a free moment.

    I wrote it as a safe practice, but there was an oversight. In the tool that builds the screen (tkinter), the only flow allowed to touch the screen’s parts is the flow that created them (the main flow), and what happens when they are touched from another flow was never guaranteed in the first place. And the act of asking with self.after(0, ...) was itself one of the operations that touch the screen’s parts.

    A way with no guarantee reaches in some environments and does not reach in others. At midday on September 14, with the Python that was on my own computer it did not reach, and with a different Python it had been reaching.

    The log lines that did not come out at midday, the progress bar, and the notice that it had finished — all of them were things asked for with that unguaranteed way of asking. The reason only the heading lines came out is that those were written in the program within the main flow.

    That afternoon, I ran a small test that AI had prepared, on my own computer. A small window appears for an instant, and it finishes in a few seconds. Running it actually showed the following.
    Requests from the main flow reach.
    Requests from the conversion flow are being silently discarded, raising no exception (notice of an error) and not being made to wait. The conversion flow itself has not stopped.

    Judging from this test, I assume that in the midday run as well, the conversion processing had proceeded to the end, and it was simply that I could not see it. Since it was a Dry Run, nothing had been written to the files either, so it was a state in which I could not even tell whether the processing had finished.

    As for how to fix this state: stop this way of asking, and that is all.
    The conversion flow only puts what it wants to convey into a queue (a box where things are stacked in order). The main flow goes to look at the box every 0.1 seconds and puts what has accumulated onto the screen itself. I changed it from asking to picking up what has been stacked.

    Why it reaches in some environments and not in others remains unconfirmed. The fix is the same either way.

    The Evening of September 14

    After the fix, on my own computer, I ran it again from the screen.

    First, I ran the folder I had prepared for checking, the one containing 10 files, as a Dry Run. The 「対象ファイル数」 (number of target files) line that had not come out at midday came out as 「対象ファイル数: 10 件」 (number of target files: 10), and all the lines after it came out too. The progress bar went all the way to full, and the run button returned to a state where it could be pressed.

    Next, I ran a folder containing 2,000 files, likewise as a Dry Run. Information on the processed files was displayed one after another in the log display area, and I could also see the progress bar partway along.

    Then, with the first folder, I set it not to include subfolders, turned off Dry Run, and ran it. The targets were the 6 files directly inside. 2 skipped, 4 converted. The ones converted were the 4 files index.html, top.html, tool.py, and common.css.

    On the evening of September 14, 2026, for the first time, the files in the folder I had prepared for checking were converted from the screen. At last, a test had been run in a form that follows the path a user takes.

    Next time, I will write about what was happening on the judging side before this fix was judged to have “passed.”


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • Stopped for Half a Year — The Story of Realizing, Only Later, That I Had Already Crossed the Wall

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 7)


    At the end of last time, I wrote this.

    With this, the implementation of utf8conv is complete. The Mac app form (.app), as I wrote two installments ago, has already been exported. What remains is not writing code but the procedures for “putting it out into the world.” The signing and notarization with an Apple Developer ID written under “Future Outlook” in the requirements document. And then deciding where to distribute it.

    Last time’s story was a record from March. And now, as I write this, it is October. utf8conv has still not been distributed.

    This time, I will write about what happened in that half year. Not a story about development, but a story about “why something I thought I had finished building did not go out.”

    What Was Left When I Wrote “Just a Little More”

    First, let me line up what was visible as of last time.

    • The code is written. The tests pass too
    • The .app for macOS has been built too
    • What remains is the signing and notarization with an Apple Developer ID
    • And then, deciding where to distribute it

    Written like this, it looks like a matter of a few more days. In fact, I thought so myself.

    There is something that was not in this list. That I found this out in September is what this installment is about.

    Why I Was Stopped for Half a Year

    The reason I was stopped is a single one. It was because I could not decide whether or not to join the Apple Developer Program. To distribute a Mac desktop app to other people, the app has to be checked as to whether it was developed in a proper environment, and that requires joining the Apple Developer Program (99 dollars a year). What I was agonizing over was not the amount itself. “Am I even the kind of person who is at a level where I can join in the first place?” “If I pay 99 dollars a year, will I be able to get a return on it?” “Can software of mine, truly developed together with AI, really get through that process?” — I was extremely skeptical about these three. The payment itself is not an amount I could not afford, but if the certification and so on did not go through, it would be wasted, and I did not know whether I could recover from there.

    Unable to reach conclusions on these, I decided to stop the work. I would resume once I had made up my mind — that is what it came to.

    Also, a different idea had come up, and the urge to hand that one over to AI quickly and confirm whether it could be realized had come over me — that too was one reason I was stopped.

    I Had Crossed the Wall While Building Something Else

    For that half year, the work of distributing utf8conv was stopped. But that does not mean my hands were idle. I built and released CubePlot, a tool for drawing 3D graphs, and separately from that I was building one more desktop app, for Mac and Windows.

    It was on August 11 that I joined the Apple Developer Program in order to distribute that desktop app.

    What joining lets you do is “signing” and “notarization.”

    • Signing: writing your name with a certificate, saying “this app is something I made”
    • Notarization: sending it to Apple’s side and having them check that nothing bad is inside

    An app that has not been signed and notarized shows the warning 「開発元が確認できません」 (the developer cannot be verified) when you try to open it on a Mac.

    And this is the thing I most wanted to write this time.

    The wall that had stopped utf8conv, I had crossed, before I knew it, while building a different app.

    Joining the Apple Developer Program is per developer, not per product. Once you have joined, it can be used as is for signing and notarizing other products too. During the half year I was stopped, intending to cross it for utf8conv’s sake, I had crossed it for a different reason. That is what it was.

    Rereading After Half a Year: The Design Was Right, and My Notes Were Wrong

    Now, from here is the main subject.

    In September, I checked the drafts of this series against the current implementation. Their content is the record from March, and half a year has passed. I needed to confirm that they did not conflict with the implementation as it is now.

    There were conflicts. Only, in the opposite shape from what I had expected.

    In the draft of the technical explanation installment, I had written this.

    utf8conv opens a file, reads only the first few hundred to few thousand bytes, and determines which encoding it is written in. There is no need to read the whole file.

    But when I open the code, this is what it says.

    raw = path.read_bytes()   # ← reads the whole file
    

    It reads all of it. There is no processing anywhere that reads only the beginning.

    (The technical explanation installment of this series has been corrected since this discovery. If you reread it now and it says it reads the whole file, that is why.)

    At first I thought, “I must have changed the implementation partway through.” In half a year, that kind of thing happens. But as I followed the records, that was not it.

    There was no record of changing the implementation partway, neither in the development journal nor in the instructions. When I went back and checked the code saved in March, as of the code saved on day two of development, that is, March 8, it was already reading all of it. Not once had it read only the beginning.

    Then where did that description come from?

    From One Line I Wrote to an Article

    I searched for the origin. I searched the utf8conv repository — the place where this project’s files and the history of their changes are kept together — and the place where the blog manuscripts are kept, for the word 「先頭」 (the beginning), and lined up the results from oldest to newest.

    1. March 8, the requirements document Rev.2 says “determine the whole from the leading bytes”
    2. The instruction text handed to AI the next day, based on that requirements document, carries the same description
    3. It is carried over into the memo organizing the discussion points, written in May
    4. The blog-material memo recorded on March 8 has the concrete expression “reads only the first few hundred to few thousand bytes”
    5. That is taken into the blog’s manuscript collection
    6. It becomes the draft, before correction, of the technical explanation installment

    Six documents. Counted as the number of times it was copied, five. And all of them were still on hand. Four in the utf8conv repository, two on the blog side. (The recorded date of the fourth memo is March 8, the same as the requirements document Rev.2. Which of these two came first cannot be told from the records.)

    In other words, one mistaken line I had written in the specification had become an article I wrote, and was about to go out into the world. The implementation had been right from the start, and only the explanation of the implementation had taken on a life of its own over half a year.

    This error was found and corrected in August. The requirements document Rev.3 of August 4 says this.

    The description “determine by looking only at the leading bytes” was an error and was deleted in Rev3. In reality, read_bytes() reads the whole file, and the whole is decoded

    But what was corrected in August was only the requirements document and the document that instructed that correction. The material memo, the manuscript collection, and the article draft were all left as they were. What is more, the requirements document itself still had a sentence derived from this misstatement, “processing speed is proportional to the number of files,” and that disappeared only on September 9. Correcting upstream does not automatically correct the downstream copies. And where the copies are, you do not know until you look.

    One more thing became clear. Among the tests, there is a test placed with a comment like this.

    Detect here a regression to an implementation that “looks only at the first N bytes.”

    It had been set up so that if I ever carelessly went back to an implementation that “reads only the beginning,” the test would fail. The implementation had been consistent from first to last. What wavered was the writing.

    In That Half Year, the Design Had Changed in Three Ways

    One more thing I learned from the comparison. During the half year that the distribution work was stopped, utf8conv’s design had changed in three ways. In terms of the revision history of the requirements document, Rev.3 of August 4 and Rev.4 of August 31.

    First. The way character encodings are assigned changed from the ground up.

    In the fourth installment of this series, I wrote this: try 16 encodings from the top in a fixed order, and adopt the first one that reads. How to decide that order was the theme of that installment.

    Now it is different. Instead of guessing by order, it asks the person using it first: “What language is this file?” Choose Japanese and there is one candidate; choose Korean and there is one. The very idea of trying everything in turn is gone.

    Moreover, Japanese alone is split into two choices: 「日本語(まずはこちら)」 (Japanese (try this first)) and 「日本語(EUC-JP:上でエラーや文字化けになる場合)」 (Japanese (EUC-JP: if the one above gives errors or mojibake)). The reason is written in a comment in the code. With a byte sequence that could be read either way, EUC-JP would succeed first, and things like Shift-JIS half-width katakana had been silently garbled. If the candidates are narrowed to one, that mix-up structurally cannot happen.

    While doing this rewrite, I had also plugged a hole I had left noted in the technical explanation installment. The story of an ISO-2022-JP file looking like “a file with nothing but ASCII” and passing straight through. Now, the processing that looks for those signal bytes comes before the UTF-8 check. Something I had not noticed when I wrote the article had been fixed half a year later, with no connection to the article. The order is the reverse: after the fix, the article caught up.

    Second. latin-1 was removed from the candidates.

    That latin-1, which I had placed in the second installment of this series as “a catch-all.” Back then I wrote, “it can read any byte sequence, so the processing does not have to stop.” And I also wrote, “this decision gets overturned later.” Here I collect on that.

    The problem was that the very state of “none of them could read it” disappears. No file being unreadable means that images, executables, everything becomes a target for conversion. The fortress meant to keep things from stopping was in fact breaking the safety valve. So I removed it.

    Third. The way of saving after conversion changed.

    Previously, the original file was moved aside into a backup folder. Now, the default is to put a mark at the front of the original file’s name and leave it where it is. The reason is simple: the file’s information, such as its creation date, is preserved. Moving it to a folder can lose that.

    None of the three appear in the March articles. Because the design did not exist in March. The half year I had thought of as “stopped” had, on the record, been properly moving.

    And There Was Not a Single Procedure for Building the Thing to Distribute

    Last, the discovery that hit hardest.

    In September, I ran an inspection of the product candidates. Not “do the files exist,” but an inspection of “actually build it, run the tests, and get one main feature working” (I did not go as far as opening the screen to check).

    For utf8conv, the result was this.

    • The tests pass (426 collected, 354 passed. The remaining 72 are skips, and zero failures)
    • The character encoding conversion actually works too (★ but the screen is unconfirmed)
    • There is not a single procedure in the repository for building a distributable (the thing bundled into a form you can hand to people)

    And this despite my having written in the last article, “The Mac app form (.app), as I wrote two installments ago, has already been exported.”

    To be precise, it is like this. PyInstaller, the tool that bundles a Python program into the form of an app, is in the list as a development tool. But there is not a single configuration file that says how to run it. There is no procedure written down, in other words.

    What Is a Spec File?

    A short detour, to write down what this “configuration file” is.

    PyInstaller is a tool you run by typing a command in the terminal. When I built the .app in March too, the procedure left in the README was a single command.

    Here is something I did not know at the time. When PyInstaller receives this command, it first writes, by itself, a blueprint called a “spec file.” And when it assembles the app, it executes not the command but that blueprint. The official documentation says this.

    The spec file is actually executable Python code. PyInstaller builds the app by executing the contents of the spec file.

    In other words, the act of typing the command was having the blueprint written automatically, and then having it executed.

    And from the second time on, you can hand it that blueprint directly.

    pyinstaller utf8conv.spec
    

    That alone produces the same thing as before. No need to remember long options. What is more, things that cannot be fully written on the command line — bundling data files in, including the parts needed at run time — can also be written in this blueprint.

    The Blueprint Had Been Set Not to Be Recorded, from Day One

    So where is that blueprint kept?

    When I looked, it had never once gone into the repository’s record. I went back through all 24 commits — a commit is the save operation of “keep the changes up to here, under this name” — and there were 0 spec files.

    The reason was simple. The .gitignore — a file for writing down “do not record this kind of file” — had this in it.

    dist/
    build/
    *.whl
    *.spec
    

    Both dist/ and build/ are things you can make by rebuilding. A spec file, too, is something you can remake by typing the command, so it was in the same row.

    And this .gitignore was written at 23:40 on March 7, 2026, in the very first commit. It is 「U1: プロジェクト基盤セットアップ」 (U1: project foundation setup). (U1 is the number I had given to the first unit of work.) The .app was built about 12 hours later.

    Here, there is something I have to write down. This .gitignore is not something I wrote with my own hands. It was created in the “project foundation setup” on day one, together with configuration files like pyproject.toml. As I wrote in the first installment of this series, that work was done by having AI move its hands.

    The setting of not recording *.spec worked exactly as written. The blueprint never once remained in the record. The command to remake it did remain in the README, but the premise “it can be remade” stands on the premise “there is someone who knows the command to remake it.” I did not remember that command, and I did not even know that such a thing as a spec file existed, until half a year later.

    A correct boilerplate that AI had put in place had hidden a single blueprint from the me of half a year later. Nobody made a mistake, and still this kind of thing happens.

    This is different from “the build is failing.” There is no place where the build is written. What remained was not the work of fixing, but the work of writing.

    In the last article, I had written that what remains is “not writing code but the procedures for ‘putting it out into the world.’” In reality, before the procedures, there was still something to build.

    What Did “Complete” Mean?

    In last time’s closing, I wrote, “With this, the implementation of utf8conv is complete.” That was not a lie. The code is written, and the tests pass.

    Only, between “it works” and “it can be distributed,” there was a distance.

    • It works (on my own computer)
    • It can be bundled into a distributable form ← ★ this was missing
    • Signing and notarization are done
    • The place to put it is decided

    When I wrote “complete” in the last article, what was done was the top line. The second line, I learned for the first time in September’s inspection, was not there. The membership the third line needs had been completed in August, for a different product.

    Lining them up like this, I can see that what I had been calling “complete” was only the top line. For someone who started building with zero programming experience, the difference between these four lines was not visible until I had finished building.

    And this distance did not close in a few days. Building took 4 days, but distributing is still not finished, even in October.

    Where Things Stand as of October

    The procedure for building the distributable was written up as a document in mid-October and handed to AI, and the first stage went through. I decided to make a Windows version as well; the materials for trying it out are consolidated into one, and it runs on Windows first. The signed and notarized version is scheduled to be tried from a download.

    Next time, I will write about what I learned before writing that procedure.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • Implementing the Declaration Rewrite — The Day I Wrote Tests as Data, Not Code

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 6)


    Last time was a technical explanation: what converting a character encoding is actually doing, and why, in a file like HTML that declares its own character encoding by itself, “I saved as UTF-8 but it’s still broken” happens. This time I return to the timeline.

    This is the story of March 9, the day after I rewrote the requirements document as Rev.2. I did two things that day. I actually built the feature I wrote about at the end of last time, the one that rewrites the declaration inside a file. And I changed the tests so that they are written as data rather than as code. After that, I will go on as far as the small additions of the following day, March 10.

    Building the Declaration Rewrite

    On this day, I added one function to the conversion internals (core.py) that rewrites declarations. In the flow of a conversion, after the byte sequence has been rewritten as UTF-8, this function is called automatically.

    What it rewrites had been written as a table in the requirements document Rev.2. What I built that day follows that table exactly.

    • HTML <meta charset> → rewrite
    • The charset in HTML <meta http-equiv="Content-Type"> → rewrite
    • XML <?xml encoding?> → rewrite
    • CSS @charset → rewrite
    • Python # -*- coding: -*- → do not rewrite

    The first four are all self-declarations saying “this file is written in this character encoding.” After the body has been rebuilt as UTF-8, if only this declaration is left behind pointing at the name of the original character encoding, the reader believes the declaration and the text comes out garbled. So they are rewritten. The last one, the declaration written at the top of Python source code, plays the same role but is not rewritten. What this line means is as I wrote in last time’s technical explanation.

    The implementation takes the form of regular expressions (a notation for writing out a pattern of characters and finding the places that match it). It searches the body of the file for the declaration line by pattern, rewrites something like Shift_JIS to UTF-8, and then saves. That day’s journal records that differences between uppercase and lowercase could be absorbed on the pattern side, and that because the attributes in an HTML <meta> tag vary in order, the pattern was designed carefully. I wrote 8 tests for this function.

    Writing Tests as Data Instead of Code

    In parallel with the declaration rewrite, the other big piece of work that day was a change to how the tests are built.

    Until then, each test had been written as a Python function, one by one. Five tests for detection, four tests for collecting the target files, and so on: one function for each thing to be checked. With this approach, if you want more tests, you have to write that much more code. As I wrote two installments ago, the test files (fixtures) had been prepared by auto-generation, 518 of them. Writing these out one at a time as test functions is not realistic.

    What I used instead was a mechanism in pytest (the tool that runs the tests) called “parametrized tests.” Roughly speaking, it is “hand it a list of data, and it repeats the same test as many times as there are items in the list.”

    In utf8conv, I set it up so that pairs — a file before conversion, and the answer file saying what it should become after conversion (.expected) — are collected automatically from the tests/fixtures/ folder and fed into this mechanism. The test itself is a single function. It checks just one thing: “does the result of converting a given before-conversion file match the contents of the answer file paired with it?” Into this function flow, one after another, the 252 pairs out of the 518 files that have an answer paired with them.

    The result: of the 252 pairs, 210 passed and 42 were skipped. Besides these, there are 2 tests confirming that files already in UTF-8 pass straight through without being converted, and 3 tests confirming that broken files are rejected. The tests up to the day before had numbered 25, so the number of tests jumped in a single day. But what grew was “data,” not “code.” There is one test function, and every time you place one more pair of answer files, the tests grow by one.

    This experience took on a slightly philosophical meaning for me. I had assumed that “the only way to add tests is to write code,” when in fact there was a world where “tests grow just by placing data.” To put it in vibe coding terms, it may be close to the idea of “expressing the specification in the form of data.” Instead of “writing the rules in words,” you “put down many examples,” and that is how you convey what you expect.

    The 42 Skipped Pairs, and the Characters I Put Back In

    The reason 42 pairs were skipped is as I wrote in last time’s technical explanation. Some of the files made in Western and Eastern European character encodings had contents only in the ASCII range, so they could not be distinguished from UTF-8, and were treated as “detected as UTF-8, no conversion needed.” That is not a weakness in detection but correct behavior, so in the README I wrote it not under Limitations but under How It Works. That much is last time’s story.

    On this day, there is a sequel to it. Into the latin-1 fixtures, I deliberately put non-ASCII characters back in (characters outside letters and digits, such as é). With contents that are ASCII only, it does not amount to a test that confirms “a file saved in latin-1 gets converted to UTF-8.”

    The Next Day, March 10 — A Small Addition, and One That Was Already In

    The next day, March 10, I ran another round of work and cleared up three small features. 「追加指定」 (add custom extension), which lets you add target extensions yourself; a feature that saves the conversion results log to a file; and a feature that converts just one file rather than a folder. All of them had been listed as “not yet started.”

    But as soon as I started, it turned out that 「追加指定」 (add custom extension) was already in. The GUI I ran on day one had had an input field for 「追加指定」 (add custom extension) from the very start. It is the field I wrote about in the first installment of this series, the one on day one’s screen. The requirements document listed it among the “things to build next,” and the real thing had long since existed. This was the only item written under “where I stumbled” in that day’s journal. I judged that no tests needed to be added.

    In the end, what I newly built that day came to two things. One is saving the log: press the 「ログを保存…」 (Save Log…) button and the conversion results shown on the screen can be written out to a text file. The other is converting a single file: choose one file from the 「ファイル…」 (File…) button, and it converts just that file without specifying a folder. As with a folder, a backup is made and the declaration rewrite runs too. I added 5 tests for these two, and reorganized the usage section of the README into four parts: folder, file, 「追加指定」 (add custom extension), and saving the log.

    How Many Days It Took, and a Look Back

    The work on utf8conv reached the declaration rewrite I have been describing in three days: March 7, 8, and 9. Including the additions on the 10th, four days. As reasons it progressed in this many days, I will list three things the records allow me to say.

    One is that the scale was small. There is one thing to do: bring the character encodings of files into line as UTF-8. That is all.

    The second is the constraint of “zero additional packages.” The policy of limiting the parts used to those that come with Python from the start was set from the very beginning of development, and is written into the requirements document as a policy. The screen is tkinter only, and the detection of character encodings is my own, without using outside parts that detect statistically. There were few things to choose from in the first place.

    The third is that I was able to rewrite the requirements document while building. As I wrote two installments ago, the requirements document was rewritten from Rev.1, written on day one, to Rev.2 the next day, March 8. The declaration rewrite I built on March 9 is an item added at that time.

    Implementation Ends Here, for Now

    With this, the implementation of utf8conv is complete. The Mac app form (.app), as I wrote two installments ago, has already been exported. What remains is not writing code but the procedures for “putting it out into the world.” The signing and notarization with an Apple Developer ID written under “Future Outlook” in the requirements document. And then deciding where to distribute it.

    Looking back now that it is complete, the development of utf8conv was, for me, “a small, fast, closed experience.” A small product that slipped in, like a breath between strokes, in the middle of a large project like DataMigrator. But what I gained was more than I expected. In particular, the vibe coding sense of “reusing a pipeline you have once pushed through on the next product” is something I felt for real for the first time with utf8conv. And this sense is sure to pay off, from here on, when I build other products as well.

    Whether utf8conv will actually be used by someone and prove useful is something I will not know until I release it. I started from the hypothesis that the problem I was struggling with must be one that someone somewhere in the world is struggling with too, but whether that hypothesis is right is something I am at the stage of confirming from here. “Building it” and “selling it” are different stories, and this blog covers only as far as the former. About the latter, honestly, anxiety is slightly ahead of confidence at the moment. But, with that included, I want to go ahead with preparing to put it out into the world as one of SRW’s products.

    The “building it” story of the utf8conv series ends here. Next time, I will talk about the work that still remains from here on.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • VS Code Was Not Lying — Digging into the Encoding Problem Until It Made Sense to Me

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.


    Series: utf8conv Development Journal (Part 5 — a technical explanation)


    This time steps away from the timeline a little. At the end of last time, I wrote that I had added one line to the background of the requirements document Rev.2: “mojibake is not fixed even when you ‘save as UTF-8’ in VS Code.” In this installment, I write about the “why.” What is actually happening when you convert a character encoding? When re-saving does not fix it, where does the cause lie? And the feature I added to utf8conv on March 9, the day after writing Rev.2, is exactly the feature for this problem.

    Let me state up front the one thing I want to say in this installment. Converting a character encoding is the work of rebuilding the contents of a file (its byte sequence). However, in a file like HTML that has written inside itself “what character encoding I am written in,” the text of that declaration stays as it is even after the contents are rebuilt. The reader believes the declaration, so even though the contents are correct, the text comes out garbled.

    A File Is Nothing but a Byte Sequence

    First, the basic premise. A file saved on a computer is, when you get right down to it, a string of numbers called a “byte sequence.” A byte is any one number from 0 to 255, and a long row of these numbers is the body of the file.

    For example, even if you save just the single character “あ” (the Japanese syllable “a”) to a text file, the file does not contain the shape “あ.” What it contains is several numbers. The agreement about which character corresponds to which set of numbers is called an “encoding” (a character encoding).

    There is more than one such agreement. The same “あ” becomes the 2 bytes 82 A0 (130 and 160 as numbers) under the agreement called Shift-JIS, and the 3 bytes E3 81 82 (227, 129, and 130) under the agreement called UTF-8. This way of writing is hexadecimal, which I also used last time. Even for the same character, if the agreement differs, the row of numbers inside the file differs.

    The reverse also happens. If you read the 2 bytes 82 A0 as Shift-JIS, you get “あ,” but if you read them as GBK (a Chinese character encoding), you get a different Chinese character, “偁.” The same row of numbers becomes a different character depending on how you read it. This is the true nature of mojibake.

    To Convert Is to Rebuild the Byte Sequence

    So what, concretely, is happening when you “re-save a file saved in Shift-JIS as UTF-8”?

    Intuitively, it may sound like nothing more than peeling off a label that says “this file is Shift-JIS” and sticking on one that says “UTF-8.” But what actually happens is the work of rebuilding the byte sequence itself, from top to bottom.

    There are three steps. First, read the original file’s byte sequence under the Shift-JIS agreement and turn it back into a sequence of characters. This is called “decoding.” Next, write that sequence of characters out as a new byte sequence under the UTF-8 agreement. This is called “encoding.” Finally, write that new byte sequence to the file.

    Inside utf8conv, what does these three things is, in effect, these two lines.

    text = path.read_bytes().decode("shift_jis")
    path.write_text(text, encoding="utf-8")

    Take the single character “あ,” for example. What is inside a file saved in Shift-JIS is the two numbers 82 A0. The decoding on line 1 turns these back into the character “あ.” The encoding on line 2 turns that “あ” into the three numbers E3 81 82 under the UTF-8 agreement, and writes them to the file. 82 A0 disappears from the file and is replaced by E3 81 82. Even the count of the numbers changes, so merely swapping a label would never get you this.

    Line 1 turns the Shift-JIS byte sequence back into a sequence of characters, and line 2 writes it out as a UTF-8 byte sequence. Two short lines, but every number inside the file is replaced. It is not a swapping of labels.

    The True Nature of “I Saved as UTF-8 but It’s Still Broken”

    Here, let me return to the problem I wrote about in Part 1 of this series: mojibake that was not fixed even after re-saving in VS Code. In the background of the requirements document Rev.2, I described this as “a mismatch between the encoding declaration and the actual encoding.”

    Some file formats, such as HTML and XML, have a mechanism for embedding, inside the file itself, a declaration that says “this file is written in this character encoding.” For HTML it is <meta charset="Shift_JIS">, for XML <?xml version="1.0" encoding="Shift_JIS"?>, and for CSS @charset "Shift_JIS";.

    These declarations are markers that tell the reading software, such as a browser, what character encoding the body of the file is written in. The reader looks at this marker and decides how to read.

    Here is the trap. An editor’s “save as UTF-8” rebuilds the body’s byte sequence as UTF-8. That is exactly the “decode, then encode” from above. However, the declaration <meta charset="Shift_JIS"> is just a string of text within the body. Even when a string is rewritten under the UTF-8 agreement, what it says (the name Shift_JIS) does not change. The body has been converted, but the declaration remains Shift-JIS. This is the “mismatch between the declaration and the actual encoding.”

    The result is a state like this.

    • The file’s actual contents (the byte sequence): UTF-8
    • The declaration inside the file: “This file is Shift-JIS”

    When you open this file in a browser, the browser reads the declaration, concludes “Shift-JIS, then,” and tries to interpret the UTF-8 byte sequence as Shift-JIS. Naturally, it does not come out as correct Japanese. The familiar mojibake screen is the result. (To be precise, a browser looks first at a marker called a BOM at the start of the file, and at the information the web server sends, before it looks at the declaration. When you open a local file directly, neither of those is present, so the declaration is used.)

    In other words, VS Code was not lying. The conversion of the byte sequence was done correctly. It just did not reach as far as the declaration. And the reader treats the declaration as the truth. This is the true nature of “I saved as UTF-8 but it’s still broken.”

    For files that carry no declaration (.txt, .md, and so on), re-saving alone solves it. Only files that have a mechanism for declaring their own character encoding — HTML, XML, CSS — fall into this trap.

    To try another kind of example, the translation of languages may come close.

    If something is written in Japanese as “私は日本人です。” (Watashi wa Nihonjin desu — “I am Japanese”), the language and the declaration of what nationality the writer is agree with each other.

    On the other hand, if it is written in Chinese as “我是日本人,” or in English as “I’m Japanese,” the meaning to be expressed — “I am Japanese” — stays the same while becoming Chinese or English, but as a declaration it says “Japanese.” If you give priority to this declaration part, then whether the text is Chinese or English, since it declares the writer to be Japanese, you treat it as Japanese. Even once you have decided to treat it as Japanese, the language actually in use is something other than Japanese, so naturally it cannot be interpreted as Japanese.

    In this example, I have swapped in language itself and meaning that carries context, so the intent is slightly different, but you can see that the cause of the problem is that there is a declaration and that it causes a mismatch.

    It Was Not Only About Browsers

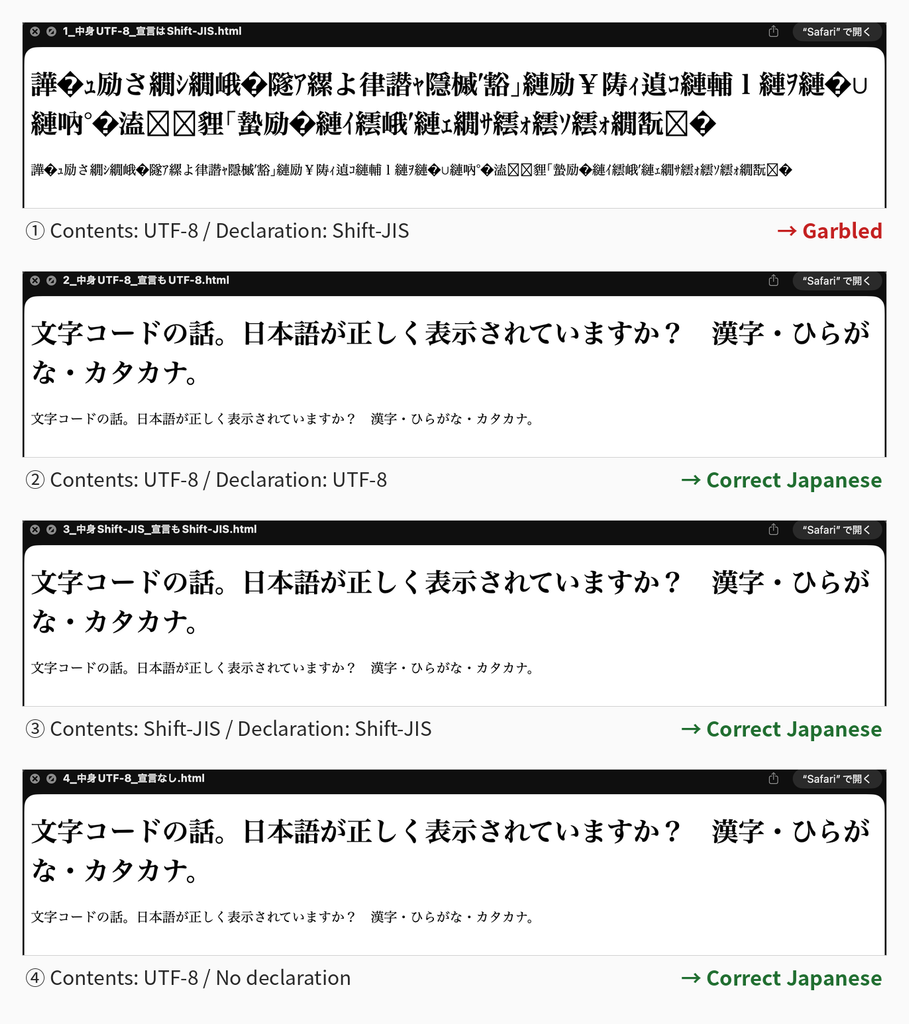
    This “gap between the declaration and the actual encoding” is not limited to browsers. As I touched on briefly in Part 1 of this series, the same thing happens in the preview that appears when you select a file in the macOS Finder and press the space bar. To confirm it, I made four files and checked.

    A file whose contents are UTF-8 and whose declaration says “Shift-JIS” — garbled in the preview too. If both the contents and the declaration are UTF-8, it reads fine. If both the contents and the declaration are Shift-JIS, that reads fine too. And the file with the declaration itself removed read correctly.

    In other words, the preview can guess correctly by looking at the contents. Even though it can guess, when there is a declaration, it believes that instead and breaks. The result is a somewhat perverse one: it displays correctly when there is no declaration.

    The four screenshots I actually took. ①, where only the declaration disagrees, cannot be read; ④, which has no declaration at all, can be read.

    Four HTML files opened in the macOS preview, stacked vertically. Only the first — contents UTF-8, declaration Shift-JIS — is a string of unreadable characters; the remaining three (contents and declaration both UTF-8 / contents and declaration both Shift-JIS / no declaration) all display the Japanese correctly
    How the standard macOS preview behaves depending on the encoding and the declaration. ②–④ show the same sentence, correctly: “A note on character encodings. Is the Japanese displayed correctly? Kanji, hiragana, katakana.” ① is the same file content, garbled.

    This Is What utf8conv Wanted to Solve

    utf8conv has a feature for this problem. I added it to the requirements document Rev.2 as “the target of the next work,” and implemented it the following day, March 9. This feature does two things.

    The first is to convert the body’s byte sequence from the detected character encoding to UTF-8 (up to here, it is an ordinary conversion). The second is to rewrite the declarations inside the file — <meta charset>, <?xml encoding>, @charset, and the like — so that they point to UTF-8. The targets of the rewrite are four extensions: .html .htm .xml .css.

    By doing these two things at the same time, it can produce the state “both the actual contents and the declaration are UTF-8.” Open it in a browser and it is not garbled.

    There are, however, declarations it does not rewrite. The line # -*- coding: shift_jis -*- that is sometimes written at the top of Python source code. utf8conv does not rewrite this line, because doing so would count as modifying source code.

    This is easy to misunderstand, so let me state it clearly. The role of this line is the same as HTML’s <meta charset>. A Python specification called PEP 263 defines it as the declaration, placed on line 1 or line 2 of a source file, of “what this file itself is written in.” That means that if you include .py in utf8conv’s targets and convert, the body becomes UTF-8 while this line remains, pointing at Shift-JIS. Python reads that file as Shift-JIS, as declared, so either it fails to read it and raises an error, or it raises no error and turns into different characters. The gap between declaration and actual encoding occurs here in just the same way.

    Also, with HTML and the like, the purpose is basically only to read the file out and display it. A program such as Python, on the other hand, is required, once read in, to “run correctly as a program.”

    At first glance it looks like merely rewriting the declaration so that it matches, but the behavior of a program with that modification in it cannot be guaranteed, and there is a considerable risk of contributing to the creation of unintended bugs. For that reason, I excluded the declaration line inside programs that are run from the targets of the rewrite.

    Later, after various deliberations, I changed it so that .py files themselves can also be converted. I assumed there would be demand along the lines of “there are many files, so I want them changed all at once.” However, when a conversion is done, the encoding of the body becomes UTF-8 while the declaration remains as it was, leaving a mismatch in place; so I decided to notify the user of that fact and prompt them to deal with it individually.

    What It Means to Read the Whole File

    utf8conv reads the byte sequence of a file it is detecting from beginning to end, not just the head. Having read it, it tries, in order, “can this be read through, without contradiction, as this character encoding?” It can happen that a file reads fine partway and then breaks down in the last few bytes, so nothing certain can be said without reading all of it. Consequently, a large file takes correspondingly more time.

    On the other hand, files outside the targets are sifted out by extension before their contents are read. Even if a 1 GB video file is mixed into the folder, no time is spent there.

    For this reason, to the “How It Works” section of the requirements document Rev.2, I added: narrow down the target folder before running; check with a dry run first; and avoid system folders such as /Library and /System (which can run to tens of thousands of files or more).

    Knowing the Limits of Detection

    utf8conv’s detection works like this: it first tries “can this be read as UTF-8?”, and if it cannot, it tries the candidates in a set order and takes the first one that can read the file as the answer.

    Here there is a limit that comes from first principles. A file consisting only of ASCII (letters, digits, and symbols) has exactly the same byte sequence whether it is UTF-8, Shift-JIS, or EUC-JP. That is because all of these character encodings use the same numbers for the ASCII range. In other words, for a file of nothing but letters and digits, “which character encoding it was saved in” cannot be distinguished in principle. Whatever tool you use, it is the same. The numbers that would serve as a clue do not exist inside the file.

    In the work of March 9, this actually happened. When I wrote a test that runs all 252 pairs of test files made the day before, some of the files made in Western and Eastern European character encodings were detected as “UTF-8.” That was because their contents were only in the ASCII range. I decided to treat these files as “skipped” in the tests.

    utf8conv treats files expressed only within the ASCII range like this as “detected as UTF-8, no conversion needed.” Since an ASCII-only file has the same byte sequence whatever character encoding it was saved in, nothing breaks by treating it as UTF-8.

    In the README, I wrote this behavior not under “Limitations” but under “How It Works.” It is not that it cannot distinguish; it is that there is no need to distinguish. Since treating it as UTF-8 is fine whatever the character encoding, it is not “failing to distinguish” but “correctly skipping.”

    Something I learned after writing this article: ISO-2022-JP, an old Japanese character encoding (the one used in email in the old days), keeps every byte within the ASCII range even when Japanese is written in it. That is because it works by inserting signal bytes before and after kanji that say “kanji start here” and “kanji end here.” In other words, though the contents are Japanese, it looks the same as the “ASCII-only file” I just described. utf8conv at this point, while it had ISO-2022-JP among its candidates, let such files pass straight through at the earlier step “it could be read as UTF-8 = no conversion needed.” I will continue this story in a future blog post.

    Coming Up Next

    Next time returns to implementation. The story of actually building the declaration rewrite described in this installment, and the story of writing the tests as data rather than as code.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • Toward a Worldwide Spec — The Day I Auto-Generated 518 Files and Rewrote the Requirements Document

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 4)


    At the end of last time, utf8conv had become “the smallest thing that’s usable for now (an MVP).” However, the candidate character encodings it tried when converting to UTF-8 were only five: the four Japanese-related ones (Shift-JIS, CP932, EUC-JP, ISO-2022-JP) and the final catch-all, latin-1 (UTF-8 is outside the candidates. Before trying the candidates, it first checks separately whether the file “can be read as UTF-8”).

    This time continues the same March 8 — the fourth round of work on that day. I did four things. I widened the candidates to 16 kinds. I exported utf8conv in the form of a Mac app (.app). I rewrote the requirements document as Rev.2. And I generated 518 test files all at once.

    Let me state up front the one thing I want to say in this installment. On the day I added candidates, it became clear that “even for the same file, the answer changes depending on the order in which you try.” I did not fix that on the detection side; I wrote it into what the tests demand, and into the “Limitations” section of the requirements document.

    Adding 11 to Make 16

    If utf8conv’s future expansion overseas is to be kept in view, I want it to handle not only Japanese but also Chinese, Korean, and Eastern and Western European character encodings. With that in mind, I decided to do “international character encoding support.” I added 11 kinds. For Chinese, GBK, GB2312, and Big5; for Korean, EUC-KR and CP949; for Cyrillic (Russian and others), CP1251 and KOI8-R; for Eastern European languages, CP1250 and ISO-8859-2; for Western European languages, CP1252 and ISO-8859-1. Together with the original five, the candidates to try came to 16.

    The ordering is: the Japanese-related ones first, followed by Chinese, Korean, Cyrillic, Eastern European, and Western European, with latin-1 placed last. utf8conv tries them in this order from the top and takes the first one that can read the file as the answer.

    The Same Byte Sequence Can Be Read Two Ways

    When I added the candidates, the tests caught on two things.

    The first was that text written in Chinese (GBK) was detected as EUC-JP (Japanese).

    Let me explain a little. The contents of a file are, when you get right down to it, a sequence of numbers (a byte sequence). For example, if you save the Chinese word “中文” in GBK, the contents look like this.

    d6 d0 ce c4
    

    This is a way of writing called hexadecimal, which expresses numbers using 16 symbols: 0 through 9 plus a through f. One byte on a computer can be written in exactly these two characters, so it has become the custom for showing byte sequences. Here, just read it as “four numbers in a row.”

    If you read this byte sequence as EUC-JP, no error occurs. It reads as the two kanji characters “嶄猟.”

    Chinese (saved in GBK)Byte sequenceRead as EUC-JP
    中文d6 d0 ce c4嶄猟
    日本c8 d5 b1 be晩云
    北京b1 b1 be a9臼奨

    GBK and EUC-JP overlap in the range of bytes they use. Since neither produces an error, if you judge only by “whether it could be read,” whichever is tried first wins. utf8conv tries EUC-JP before GBK, so the Chinese file was answered with “this is Japanese.”

    What I fixed at this point was not the detection, but the test. I changed the result the Chinese test demands from “detected as GBK” to “detected as something that is not UTF-8, and the contents can be read out.”

    The second was the test with the four bytes 80 81 82 83. Until then it had been read as latin-1, but now it came to be read first by the newly added CP1251 (Cyrillic). Here too, I changed the test, to “it is fine as long as one of the final catch-alls can read it.”

    In that day’s work, I sorted these two out as follows. In detection where the order of trying decides the answer, every time you add an encoding, it affects the tests that came before. As long as we do not use an additional part that detects statistically, checking “that it can be read out correctly as something that is not UTF-8” holds up better than “hitting the exact encoding name.”

    Looking back now, the second one had a sequel. Three of the added ones — KOI8-R, ISO-8859-2, and ISO-8859-1 — can, like latin-1, read any byte sequence whatsoever. One of them answers “I could read it” first, so latin-1, at the very end, never gets its turn anymore. At this point, the catch-all was not working as a catch-all. How that story was settled, I will cover in a future blog post.

    Exporting as a Mac App

    The next task was exporting utf8conv in the form of a Mac .app, using a tool called PyInstaller. A .app is that thing with an icon that sits in the Mac’s Applications folder. Once this exists, just double-clicking in the Finder opens the utf8conv screen.

    This work of assembling the code you have written into a single bundle you can hand to someone is called a build. The finished bundle, for its part, is a distributable. These two words will come up again and again from here on.

    PyInstaller went into the category of tools used only during development, the same as pytest and the like.

    The Tcl/Tk story also had a sequel. As I wrote in Part 1 of this series, on day one the Python that uv provides did not include Tcl/Tk (the part tkinter uses to draw the screen), so I switched to the Homebrew version of Python to get it running. PyInstaller found Tcl/Tk on its own from that Homebrew version of Python and packed it into the .app along with everything else.

    On this day, dist/UTF-8 Converter.app came into being. I added the export command to the README.

    Rewriting the Requirements Document as Rev.2

    An hour later, I rewrote the requirements document from Rev.1 to Rev.2. Compared with Rev.1, written the day before, there were four main changes.

    The first is the background. To the list of situations where mojibake occurs, I added “cases that are not resolved even when you tell an editor such as VS Code to ‘save as UTF-8’ (a mismatch between the encoding declaration and the actual encoding).” This is the problem I ran into first, the one I wrote about in Part 1 of this series.

    The second is the intended users. Rev.1 listed three: “Japanese-language users,” “multilingual users,” and “non-engineers.” In Rev.2, I added a fourth: “developers, such as Vibe Coders.” These are the people who, even when an AI prompts them to re-save as UTF-8, find that it does not fix things.

    The third is the plan for the next work. I added a feature for rewriting the character-encoding declaration written inside a file, under the number F-14 (a serial number assigned to each feature), and made it the target of the next work. At the same time, I marked this day’s international character encoding support (F-10) as “done.”

    The fourth is that I newly created the “How It Works” and “Limitations” sections. In the limitations table, I wrote the two items corresponding to what the tests had caught that day: “GBK and EUC-JP overlap in byte range, so short texts can be mistaken for one another” and “candidates earlier in the trial order take priority.”

    518 Test Files

    Saved at the same time as the requirements document were the test files (fixtures). Rather than making them by hand, I ran a single generation script that Claude Code wrote, and made them all at once. The script is built only from parts that come with Python from the start.

    Here is what’s in it. 14 kinds of character encoding × 3 kinds of text × 6 kinds of extension (.txt .html .xml .css .csv .md), each as one pair: the file before conversion, and the answer file saying what it should become after conversion (.expected). That makes 504. To that, 12 files that are UTF-8 to begin with, and 2 broken files. That comes to 518 in total. The ones paired with an answer file number 252 pairs.

    These 518 files will play an active part in the blog posts that follow. I will leave that story for later.

    At the End of That Day

    The work of this installment was saved at 11:41 and 12:41 on March 8. The tests came to 25, all passing. That is the previous 23, plus one Chinese test and one Cyrillic test.

    Coming Up Next

    Next time steps away from the timeline a little. Why is it that, as I added to Rev.2’s background, mojibake does not get fixed even when you “save as UTF-8” in VS Code? I will write about the mechanism of character encodings itself.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • Completing the MVP — When Detection Cannot Be Perfect, Show the Work and Let a Human Check

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 3)


    Last time, we got as far as splitting utf8conv’s conversion internals (the core) and its screen (the GUI) into separate files, so that tests would be easier to write. This time picks up from there. The date is the same as last time: March 8 (a Sunday). In this series I call it “day three,” but strictly speaking, it was the third round of work (session) carried out on that same day.

    If I had to give day three’s work a title, it would be “GUI completion, integration tests, MVP finishing touches.” MVP is an acronym for “Minimum Viable Product,” and it means “the smallest thing that’s usable for now.”

    Let me state up front the one thing I want to say in this installment. On that day, utf8conv could not make its character-encoding detection perfect. Instead, I made what it was doing visible on screen, and shaped it so that a person could check before anything got rewritten.

    That is what the MVP consisted of that day.

    Homework from Last Time — Showing Progress on Screen

    The first item on the “next things to do” list I left at the end of the previous session was “brushing up the GUI (progress bar, status improvements, etc.).” That’s where I started on this day.

    I did three things.

    First, I put the progress bar (a horizontal bar that shows how far along things are) on the same row as the run button. Second, I moved the one line that reports the current state (the status bar) to the very bottom of the window, and during processing I made it show which item out of how many it’s on — for example, “Processing… 3/10 items.” Third, I finished the color coding of the log. Converted files are green, dry run (a trial run that doesn’t actually rewrite anything and only checks what would be converted) is blue, errors are red, and headings are yellow. I also prepared gray for skips. However, skipped files weren’t logged one by one; the design was to output only a count at the end, like “UTF-8 (skipped): ○ items,” so a gray line never actually appeared on screen.

    All three were work on the screen side; I didn’t change the way conversion itself works. It was work to get “what the conversion is doing right now” in front of the user’s eyes.

    Only the One in Charge of the Screen Touches the Screen

    Let me take a moment here to talk about how things are put together.

    utf8conv runs its conversion processing on a “separate thread.” A thread is a flow of work that proceeds side by side with others inside a program. If there’s only one flow, then while the conversion is running, redrawing the screen and responding to buttons have to line up behind it and wait. So the conversion is handed off to a separate flow, and the screen’s flow is kept free.

    This structure — the screen part and the conversion processing on separate threads — wasn’t something added on this day. It was already that way in the code Claude wrote on day one (March 7).

    The tool that builds the screen is tkinter (pronounced “tee-kay-inter”; a collection of parts for building screens that comes with Python from the start). On this day, I decided to leave progress-bar updates to the main flow as well. This is so that tkinter can be used safely from more than one flow. The conversion flow doesn’t touch the screen directly; instead, using the form self.after(0, ...), it asks the main flow, “Please display this.” The side that was asked carries it out when it has a free moment.

    This way of asking was also already in the day-one code, in two places: when outputting a line of the log, and when announcing that everything had finished. On this day, I added one more — progress-bar updates — using the same way of asking.

    Along with that, I also added one opening on the conversion-internals side (core.py) for reporting progress. Because I made this opening something “you can use or not use,” not a single one of the tests I wrote last time had to be changed.

    Tests as a Full Run-Through

    On this day, I added five “integration tests.” Whereas last time’s unit tests checked the parts one at a time, integration tests check a whole sequence with the parts connected together. In theater terms, it’s the equivalent of a full run-through rehearsal.

    The five tests cover the following five things:

    1. A Shift-JIS file gets converted to UTF-8
    2. In a dry run, files are not rewritten
    3. A backup gets created
    4. Files that are already UTF-8 get skipped
    5. And a folder with mixed character encodings can be processed all the way through

    In every case, pytest (a tool that runs tests automatically) checks things by calling the conversion-internals functions directly, without opening the screen. Because I’d separated the internals from the screen last time, it had become possible to test the whole flow without launching the screen.

    With this fifth test, I stumbled once.

    A short piece of text written in EUC-JP was detected as Shift-JIS. utf8conv at the time was built to try candidate encodings in a fixed order and take the first one that could read the file as the answer. In that order, Shift-JIS comes before EUC-JP. A short EUC-JP text can sometimes be read as Shift-JIS as well.

    What I fixed at that point was not the detection, but the test. I changed the result the test demands from “which encoding it was detected as” to “the converted file can be read as UTF-8,” and got it to pass that way.

    Where to Catch What Cannot Be Fully Fixed

    About this stumble, the work that day sorted things out as follows. Misdetections like this are inherently unavoidable unless you use an additional part that detects statistically. And since we have decided not to use additional parts, the flow in which the user checks the results with a dry run becomes important.

    From the very beginning, utf8conv had a rule that it would run using only the parts that come with Python out of the box (I called this “zero additional packages”). Within that rule, detection cannot be made perfect. So on this day, I decided to put a place for checking not on the detection side, but on the user’s side. In the instruction manual (README) I wrote that day, I also included “Dry run first — check only by default. Actual conversion only when explicitly instructed.”

    Reading it back now, that day’s work looks connected by a single line. Show the progress, color the log, and make what’s happening visible on screen. Before rewriting anything, have a person check with a dry run. In other words, on the premise that detection can be wrong, I prepared a place where mistakes can be noticed.

    Running a Dry Run on My Own Folder

    In this session, I also tried it on a real folder of my own. The target was the SRW (Soul Resonant Works) folder, ~/Documents/SRW, which contained 51 files. Running it as a dry run, all 51 files were detected as UTF-8, and none needed converting. Since it was a dry run, nothing was written to the files.

    Finishing Touches — CI and README

    Finally, there were two small finishing touches.

    One was revisiting the CI settings. CI (continuous integration) is a mechanism that automatically runs the tests every time you send code to GitHub, the place where the whole set of code is kept (the repository); here, it uses a service called GitHub Actions. This had been set up on day one, and at that time it was configured to run the tests on two versions of Python: 3.8 and 3.12. In the previous session, I had aligned the whole project on Python 3.12, so on this day I narrowed CI down to 3.12 only.

    The other was writing a new README (the instruction manual placed at the very top of the repository). It sums up on a single page what the tool does, which character encodings it supports, and how to launch and use it.

    At the End of That Day

    The work of this session was saved at 8:49 on March 8. The previous session’s work had been saved at 8:30.

    At this point, there were 23 tests in total, all passing. The breakdown: 17 unit tests from last time, 1 version check from day one, and 5 integration tests from this day. Of the conversion internals (core.py), the proportion of lines that actually ran during the tests (coverage) was 95%.

    utf8conv at the end of this day was in this state: you pick a folder, check with a dry run what would be converted, and when you actually convert, the original files remain as backups, and you can watch it all happen through the progress bar and the color-coded log. There were still things it didn’t have. The candidate encodings to try were just five: four Japanese-related ones and the final catch-all (latin-1). There was no saving of the log, and no feature for picking just one file and converting it.

    Coming Up Next

    Next time continues the same March 8. It’s the story of adding 11 more candidate encodings — Chinese, Korean, Cyrillic, Eastern European, and Western European — for a total of 16. The story of using a tool called PyInstaller to export utf8conv in the form of a Mac app (.app). And the story of rewriting the requirements document as Rev.2 and automatically generating 518 test files all at once.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • Separating the Core from the GUI — The Day I Changed the Design for Testing

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 2)


    Last time, I wrote about utf8conv’s first day. It ended at the point where, despite losing half a day to the compatibility problem between uv and tkinter, I’d managed to get at least as far as “an empty window opens, and you can pick files and do a dry run.” This time is the story of the following day — day two.

    As the title says, the theme of that day was a design change: “separating the core from the GUI.” Honestly, it’s a little embarrassing for someone with no programming experience to talk about “redoing the design.” Even so, the sense that “if I keep growing the day-one code as it is, I’ll hit a dead end” is something you can vaguely pick up on once you’re actually doing the work, even as a non-engineer. I think this installment is worth writing as a way of bringing that vague sense into sharper focus.

    A Bad Feeling Was Mixed into the Day-One Code

    What I had at the end of day one was a single file called utf8_converter_gui.py. Inside that one file, everything was bundled together: “a function that detects the character encoding,” “a function that gathers the target files,” “a function that actually does the conversion,” “the part that builds the GUI with tkinter,” and “what happens when a button is pressed.”

    A function is a single chunk of work that’s been given a name so it can be called from outside. If you ask for it by name — “detect the encoding of this file” — you get an answer back without needing to know what goes on inside. Think of it like cutting out one step of a recipe and giving that step its own name.

    It works. And since it works, I could have kept adding features to it as it was. In fact, on day one, when I asked Claude Code, “Shall we grow this a bit more and add a real conversion mode and a backup feature?”, the answer came back, “Yes, we can.”

    But when I reported that exchange to the Claude.ai side (the chat version of Claude), a slightly different perspective came up. “As things stand, you’d have to launch the GUI every single time just to check whether the conversion logic works. Doesn’t that make tests hard to write?”

    Now that it had been pointed out, it was exactly right. In the current structure, the only way to check whether a conversion works correctly was for a human to click a button with the mouse. Even if I tried to automate an action like “convert a Shift-JIS file and check the result,” the GUI sitting in the middle meant it couldn’t easily be turned into a script (something like a written procedure that runs automatically from top to bottom, without waiting for anyone to operate it). In other words, it was a structure that didn’t get along well with the whole idea of automated testing.

    I’d faintly sensed this “tests are going to be hard to write” feeling myself on day one. But I’d left it alone, thinking, “Tests can wait.” Claude.ai didn’t let that slide, and gave me a gentle push: “If you separate them now, things will be easier later.”

    What One Word, “Separation,” Really Means

    The structure Claude.ai proposed was simple. Split the file in two. One is core.py, dedicated to logic — everything that “works without opening a screen,” like encoding detection and the conversion process, goes in there. The other stays as utf8_converter_gui.py, and keeps only the part that builds the screen with tkinter and the part that calls core.py when a button is pressed.

    According to Claude.ai, this way of thinking — “separating into layers” — is one of the classic basic patterns in software engineering. It also explained that this is essentially the same thing as the three-layer architecture — “GUI layer, business logic layer, data access layer” — that I’d been designing for DataMigrator up to the previous articles. The difference is the order: with DataMigrator, I split things into three layers at the design-document stage, whereas with utf8conv, I wrote everything as one piece first and split it apart afterward.

    At that moment, one thing clicked for me. There are probably people who can write things cleanly separated from the very start, but when you write your first GUI app on your own, it inevitably ends up as one lump at first. Then, somewhere around the point where it starts working, you realize “this might not be good enough,” and you end up splitting it again. This redo isn’t a “failure” — if anything, it’s just part of the normal development process. Naturally, the same thing happens in vibe coding too.

    Giving Functions Precise Names Again

    While doing the separation, there was one more small discussion: about function names.

    In the day-one code, the main processing was bundled into a function called detect_and_convert. As the name says, it’s a function that does both “detect” and “convert.”

    As the separation work went on, Claude.ai pointed out, “This function name doesn’t make its responsibility clear.” “Detecting” and “converting” are separate responsibilities. For example, in dry run mode you only want to detect. In real mode, you take the detection result and convert as well. A function that does both ends up branching internally, which makes it harder to read. In that case, it’s better to split the function in two and give each its own name.

    As a result of that discussion, the functions were organized like this: detect_encoding(path) is a function that only detects the encoding and returns it. run_conversion(...) is a function that actually runs the entire conversion process. The two combine to handle both the dry run and the real conversion.

    A “discussion about function names” may sound technical and dull, but for me it was a small discovery. A function name is “a signboard that tells others (or your future self) what that code does,” and if the lettering on the signboard is vague, the work inside becomes vague too. There’s something a little similar here to the feeling of deciding on the title of a stage play or the name of a band’s song. Once the title is settled, the content stops wobbling. I found myself oddly convinced that function names in software had the same effect.

    The latin-1 Fallback as a “Catch-All”

    While doing the separation, I also sorted out the encoding-detection logic. Since utf8conv follows the zero-additional-packages policy, high-accuracy automatic detection like chardet isn’t available. Instead, it detects with simple logic: “try several encodings in a predetermined order, and adopt the first one that reads successfully.”

    The order goes like this. First, it tries whether the file can be read as UTF-8. If it can, that file doesn’t need converting, and that’s the end of it. Only when it can’t does it start trying the candidate list from the top, in order. My initial list was something like “Shift-JIS, CP932, EUC-JP.” If the target was Japanese files, that seemed like plenty.

    But here I noticed something: the problem that if it ran into a file that “can’t be read with any of the encodings,” processing would stop. An ordinary text file should almost certainly be readable with one of them, but there’s a chance that, very rarely, a file comes along where “every one of them errors out.”

    The solution that came up was the idea of placing an encoding called latin-1 (ISO-8859-1) at the very end of the trial order. latin-1 maps every byte (0x00-0xFF) to some character, so it has the property of “being able to read any byte sequence without raising an error.” In other words, if you keep it there as the very last fallback — a backup measure you prepare for when all the main candidates have failed — you can at least prevent the situation of “processing stopping.”

    However, when a file is forced through latin-1, the characters may not be accurate. If a file that was really Japanese gets read as latin-1, a garbled result gets output as “converted.” So latin-1 is strictly “the last-resort fallback for when nothing else could read it,” and in day-to-day use the expectation is that files get read by the Japanese encodings earlier in the list.

    This, too, was something where I only thought “I see” once it was pointed out to me. The idea of “deliberately putting a weak rule at the end” simply wasn’t in me. I came to vaguely understand that design isn’t just lining up the strong parts — it’s work that includes deciding where to place the weak parts, too.

    ★ That said, let me say up front: this decision gets overturned later. Keeping latin-1 there makes the state of “nothing could read it” itself disappear, which creates a different problem — the tool silently converts even files that aren’t text. Today’s utf8conv doesn’t include latin-1 as a candidate. I’ll write about how that came about in a later installment.

    The [build-system] Section — an Unglamorous Trap

    Let me write about one more pitfall I ran into that day. Technically it’s a very small thing, but it left an impression on me.

    After separating the core from the GUI, at some point that day, I got an error where import utf8conv failed.

    ★ To be honest, I couldn’t pin down whether this happened right after the separation work or a bit later that same day. When I cross-checked the records from that time while writing this article, two records said different things (the work log said it was during the later work; the summary said it was during the separation work). That day, I ran three sessions all within the same March 8, and the boundaries between them have blurred. Either way, it’s something that happened that day and got resolved that day.

    I’ll start from digging into the cause.

    First, there’s a file called pyproject.toml. It’s a file that gathers a project’s settings in one place — the project’s name, its version, the parts it needs, and so on. And uv (pronounced “you-vee”) is the tool that also appeared last time. It prepares Python itself and the parts you need, and runs your program.

    The single line import utf8conv means “load the bundle named utf8conv.” This “bundle” is called a package.

    The problem was that utf8conv’s pyproject.toml had no section with the heading [build-system]. Roughly speaking, this section is a statement that says, “This folder can be assembled into a distributable part.” uv uses whether this statement is present to decide “whether it’s okay to treat this as a package.” If there’s no statement, it considers “this isn’t a package,” so import utf8conv can’t find where to go, and you get an error.

    What’s interesting is that I had never once run into this problem on the DataMigrator side. When I later lined up the two pyproject.toml files side by side, DataMigrator didn’t have [build-system] written in it either.

    Instead, in the test settings, there was just one single line written like this:

    pythonpath = ["src"]

    It means “the main body of the program is inside a folder called src.” Before starting the tests, the tool that runs them (pytest) builds a list of “places to look for the main body” (the search path). This one line adds the src folder to that list. Then import utf8conv ends up in a state where it gets found even without being stated as a package, because the tool has been told directly where to look.

    Either state that it’s a package and let it be found, or tell the tool directly where to look. Either way, the test’s import goes through. However, the latter (pythonpath) only works while the tests are running — it has no effect when people use what you’ve distributed. DataMigrator happened to get through with the latter, and utf8conv had neither.

    In other words, I had simply been sidestepping the same problem by a different method, by chance. Even though utf8conv was started using DataMigrator as a template, it hadn’t inherited that one line. And I hadn’t noticed on my own that it hadn’t been inherited.

    The reason this was a slightly painful experience is that what tripped me up was the assumption that “it worked in DataMigrator, so it should be fine.” Carry the success of your first project straight into your second, and you won’t notice the differences in the settings files. Looking back, “the second project leans too heavily on the success of the first” may be a lesson that applies to anything, not just vibe coding.

    The End of Day Two

    By the end of that day, the core and the GUI had been separated, the conversion logic had proper tests, the latin-1 fallback was built in, and the [build-system] trap had been dealt with. 17 tests, all passing. Test coverage for core.py: 95%. I still don’t properly understand what the numbers mean, but I do at least understand that “apparently it’s high.”

    Compared to day one, as code it was an unglamorous kind of progress. No new features had been added, and from the user’s point of view, nothing had changed. Even so, the internal structure had changed a great deal, and from here on it had moved into a state where “features are easy to add,” “tests are easy to write,” and “bugs are easy to find.”

    Day one was “build something that works”; day two was “reshape it into a form that’s easy to grow.” Thinking back, I believe that order was just right. If I’d tried to write it in an “easy-to-grow form” from the start, I probably wouldn’t have had anything working by the end of day one — and even if I had, I’d surely have been working without any confidence that “this is the right way.”

    Coming Up Next

    Next time (UC03) is utf8conv’s third day. In terms of the date, it’s actually the same March 8 as this one. This is the day the MVP (minimum viable product) finally gets completed. The themes are: showing the progress of the conversion on screen, writing integration tests to “check the whole flow without launching the GUI,” and the episode of what happened when I ran a dry run on my own real data (the SRW folder) for the first time.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/

    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • The Day utf8conv Was Born — VS Code Wasn’t Lying, and the Mojibake Wouldn’t Go Away

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: utf8conv Development Journal (Part 1)


    Starting with this installment, I’m beginning the development journal for another product that grew up alongside DataMigrator: “utf8conv” (UC for short).

    utf8conv is a very simple GUI tool that does nothing more than batch-converting files saved in a non-UTF-8 encoding into UTF-8. The name is exactly what it sounds like: “utf-8 converter.” Unlike DataMigrator, there’s no lengthy design document behind it, and in scale the two aren’t remotely comparable — utf8conv is much smaller.

    Still, being small didn’t mean it was easy. Right from day one I ran into a compatibility problem between uv and tkinter that ate half a day, and partway through I struggled under a “zero additional packages” constraint I’d set for myself — there were a fair number of stumbles along the way.
    This first installment starts with the story of why I decided to build this tool in the first place.

    While Talking with Claude, Mojibake Was Quietly Happening

    Around February 2026, alongside developing DataMigrator, I was also doing other work while chatting with Claude — tweaking HTML files here and there, tidying up old documents, that kind of miscellaneous task.

    One day, in the middle of asking Claude for advice on something, I found a garbled file on my PC. Opening it, the Japanese parts had turned into something like “譁?ュ怜喧縺” — a string of symbols that unmistakably screamed “the character encoding is broken.” Having used a Mac for 20 years, this kind of mojibake is a familiar sight I’d run into more than a few times.

    Normally I’d have shrugged it off with an “ugh, again” and dealt with it however. But this time, since I happened to be in the middle of migrating data from my old iMac to a MacBook Pro, and had Claude on hand to ask, I tried “How do I fix this file?” Claude’s answer was straight out of the textbook: “The original file is probably saved in a different encoding, like Shift-JIS. Please re-save it as UTF-8 in VS Code.”

    So I did as told: opened it in VS Code, chose “Save with Encoding” → UTF-8, saved it, and reopened it in the browser.

    —It didn’t fix it.

    On screen, the mojibake was still dancing around, unchanged. VS Code’s own status bar at the bottom said “UTF-8,” so the file was surely UTF-8 now. When I told Claude, “I saved it but it’s still not fixed,” Claude thought for a moment and suggested, “Try explicitly specifying the encoding again when you reopen and save it.” I tried that too. Still no fix.

    At this point, doubts were starting to creep in: “Is this a VS Code bug?” “Is the AI telling me something wrong?” Doubting one or the other is one thing, but once you start doubting both at once, you lose your footing entirely.

    So, What Is a Character Encoding, Anyway?

    Let me back up for a moment and lay out some groundwork.

    Inside a computer, every character is stored as numbers — a sequence of bytes. The rule for how to read that byte sequence and map it to characters is what we call a “character encoding.” There isn’t just one such rule; many have been created over the years, for different languages and eras — Shift-JIS or EUC-JP for Japanese, GBK for Chinese, CP1252 for Western European languages, and today’s standard, UTF-8.

    The same character will produce a different byte sequence depending on which rule you use. Put the other way around: read the same byte sequence under a different rule, and you get something completely different. That’s mojibake.

    Let’s actually try it. Take a string saved under one language’s character encoding, then read it as if it were a different language’s encoding, and here’s what you get:

    Below, a Japanese file is read as Chinese (GBK), a Chinese file as Japanese (EUC-JP), and a German file as Cyrillic (CP1251).

    Japanese こんにちは 文字化け     →  偙傫偵偪偼 暥帤壔偗
    Chinese  你好 世界 编码          →  低挫 弊順 園鷹
    German   Grüße Straße Fußball  →  GrьЯe StraЯe FuЯball

    Look at the German example. Grüße has become GrьЯe. The alphabetic letters survive intact; only the characters carrying an umlaut or an eszett break, turning into Cyrillic letters. Unlike the Japanese case, where the whole string turns unreadable, here only part of it corrupts. Exactly which parts the two rules share, and which parts differ, shows up directly in the result.

    And the mojibake that opened this article runs in the opposite direction. Take something saved in UTF-8 and read it as if it were Shift-JIS, and you get this:

    Japanese "mojibake" (文字化け)  →  譁蟄怜喧縺

    In both directions, the file itself isn’t broken. The byte sequence is intact, safely saved exactly as it was. What’s broken is the “how to read it.”

    The Cause: A Mismatch Between the Byte Sequence and the Declaration

    Digging into the cause together with Claude, here’s what it eventually turned out to be.

    The problem file was an HTML file. HTML files carry a declaration line near the top of the file that says, in effect, “this file is written in this encoding” — specifically, something like <meta charset="Shift_JIS">. The browser sees this declaration and decides, “ah, then I’ll read it as Shift-JIS.”

    When you choose “Save with Encoding: UTF-8” in VS Code, the file’s contents — the actual byte sequence — really are converted to UTF-8. VS Code isn’t lying about that part. But the line that says <meta charset="Shift_JIS"> is left exactly as it was.

    That’s because an editor’s “save with a different encoding” feature converts the file’s byte sequence — it doesn’t read the document’s contents and rewrite them. So the string <meta charset="Shift_JIS"> just gets stored, unchanged, inside a UTF-8-encoded file.
    And I don’t think that’s careless of the editor — I think it’s the correct behavior. An editor that took it upon itself to rewrite the body text because “this declaration doesn’t seem to match reality, so I’ll fix it for you” would be far more alarming.

    Still, the upshot is that the file is left holding nothing but a contradiction.

    The result is a mismatch like this: the file’s actual contents are UTF-8. But the top of the file declares “this is Shift-JIS.” The browser trusts the declaration first. Believing it’s Shift-JIS, it tries to interpret the UTF-8 byte sequence as Shift-JIS. Naturally, the result isn’t meaningful Japanese. That result is the mojibake from the start of this article.

    The moment I heard this explanation, two thoughts rose up in me at once: “I see,” and “wait, couldn’t this be turned into a tool?” The problem I’d run into was probably one that plenty of VS Code users out there, somewhere, had also run into — and given that it even included the situation of “an AI kindly walking you through the wrong fix,” it seemed like something with real reproducibility. In particular, since I was already building DataMigrator, a product for organizing and migrating data files, with the underlying premise of getting file migration between my own Macs properly sorted out, I was going to need to correctly interpret the encodings of a large, disorganized pile of files anyway. That’s also where requirements like being able to do a dry run in advance, actually changing the encoding properly, handling a large number of files at once, and having a safety net to revert if needed, all found their way into the spec.

    To begin with, a tool that just batch-converts files from non-UTF-8 to UTF-8 is the kind of thing that could reasonably have existed for a long time already. But one that’s a GUI, needs no extra installation, can safely do a dry run (check only), and correctly rewrites HTML/XML declarations too — all of that together — I couldn’t find, within the range I searched.

    By the way, this problem — mojibake caused by a mismatch between the declaration and the actual encoding — wasn’t limited to browsers. The same thing happens in the Quick Look preview you get on macOS Finder by selecting a file and pressing the space bar. I confirmed this later by making four test files.

    A file whose contents are UTF-8 but whose declaration says “Shift-JIS” — garbled, even in Quick Look. A file where both the contents and the declaration are UTF-8 — readable. One where both are Shift-JIS — also readable. And a file with the declaration removed entirely — readable, correctly.

    In other words, Quick Look can actually work out the right answer just by looking at the contents. Yet even though it can work it out, when a declaration is present, it trusts the declaration instead and breaks. It displays correctly only when there’s no declaration at all — a slightly perverse result.

    From here on, this is less about character encoding itself and more about how the software is built. Software that handles character encodings is, for the most part, built to “auto-detect by default, but let you choose manually if needed.” Browsers work this way too. But the lightweight preview feature built into the OS — the one that doesn’t even count as launching an app, that opens instantly when you select a file — doesn’t seem to have that manual entry point anywhere. Maybe it exists somewhere if I looked hard enough. But the act of hunting for it is a hassle in itself, and even if I found the setting and changed it, some other encoding would stop displaying correctly instead — which would defeat the purpose.

    Rather than fiddling with the display side to fix it, fix the file itself. That, in the end, is what utf8conv is trying to do.

    UC’s Direction

    And so, right as DataMigrator’s M1 wrapped up, another small project — “utf8conv” — got underway.

    I wrote a requirements document for it too, but it never grew past 30-plus chapters the way DataMigrator’s did. It’s a modest requirements document, running to just a few chapters at most. Even so, I settled a few important policies right at the start.

    The first was “zero additional packages” — a constraint that everything had to be done using nothing but Python’s standard library. I initially considered using a well-known library called chardet for encoding detection, but I judged that skipping chardet would buy me benefits like “it runs the moment it’s installed,” “no dependency headaches,” and “distribution stays simple.” Detection accuracy might suffer a little as a result, but I figured I’d make up for that with the “try encodings in order from the top” approach described later.

    The second was “dry run first.” By default, the tool doesn’t convert anything — it just runs in a mode that logs what would happen if you converted, and only performs an actual conversion once the user explicitly chooses “really convert.” Just like DataMigrator’s “never delete” philosophy, this leans toward the safe side. Since undoing a character-encoding conversion once it’s done is a hassle, I judged that a confirm-first mechanism was indispensable.

    The third was “automatic backups.” When an actual conversion runs, the pre-conversion file is automatically moved into a backup folder. Even if a user chooses to skip the dry run and go straight to a real conversion, having a backup means they can still roll back — a last line of defense.

    Written out, these three policies come to only three lines, but they ended up defining utf8conv’s character down the line.

    On Day One, uv and tkinter Get Into a Fight

    Once the requirements document was done, I started actually moving my hands in Claude Code. Same as with DataMigrator: create the project’s box, spin up a Python environment, get a minimal GUI showing — that route. For the GUI, in keeping with the zero-additional-packages policy, I decided to use tkinter from Python’s standard library.

    But when I tried to run it, the window wouldn’t open. The error wasn’t particularly helpful either — all I got back was a message to the effect of “Tcl/Tk not found.”

    Having Claude Code dig into it, the cause became clear. uv (the Python environment manager I’d adopted during DataMigrator’s M1) ships its own Python binaries, and those binaries don’t bundle Tcl/Tk — the GUI library tkinter relies on internally. The Python that uv distributes is, strictly speaking, “just the Python interpreter” — it doesn’t include GUI-related extra runtimes. That’s a reasonable design choice on uv’s part, but it’s a trap if you’re trying to use tkinter.

    The fix was to install Python and python-tk via Homebrew, then rebuild uv’s virtual environment on top of that Homebrew Python. Written as commands, the flow looks roughly like this:

    brew install python@3.12 && brew install python-tk@3.12
    uv venv --python /opt/homebrew/bin/python3.12

    Written down, it’s only a couple of lines, but it took about half a day of trial and error to pin down the cause. Neither uv nor tkinter is at fault — it’s the specific combination that’s unusual, the kind of problem that’s genuinely hard to reach on a first encounter.

    Still, this experience paid off later. From then on, every Python project with a GUI — both utf8conv and DataMigrator — got standardized on this “uv virtual environment built on Homebrew Python” setup, and I never ran into the same problem again. One more piece of experience banked, so I wouldn’t hit the same wall twice.

    The End of Day One

    By the end of day one, a directory structure suited to software development was in place, and the source file utf8_converter_gui.py was up and running.

    Launching utf8_converter_gui.py opened a tkinter window. The conversion logic itself was already written by this point. I could already select which file extensions to target for conversion, and there was already an “add custom extension” input field where I could add my own. On top of that, the GitHub Actions test automation was running, and the first push to the private repository was done.

    That said, the current source code has the conversion logic and the GUI mixed together in a single file. In this shape, there’s no way to pull out just the conversion logic and verify it on its own. In fact, the only test I managed to write that day was a single one checking whether the version number could be read correctly. Splitting these apart so each piece could be tested individually — that became the next day’s homework.

    Oddly enough, I didn’t get the same heavy sense of “taking the first big step into a large development effort” that I’d felt when M1 wrapped up on DataMigrator. utf8conv’s first day felt lighter than that — more like an oddly optimistic “maybe this’ll be done in three days.” Maybe it’s because the smaller scope let me picture the finished product right away.

    And in fact, utf8conv’s development would go on to produce a working MVP within a genuine handful of days after this. Three days including a weekend, six chat sessions (U1 through U6), and all the features were implemented — that was the pace. Along the way, I went through a few design decisions that pushed a bit further than typical vibe coding, like “separate the core from the GUI,” “put the latin-1 fallback last,” and “write tests as data instead of code.” I’ll get into those starting next time.

    Coming Up Next

    Next time is the story of utf8conv’s second day (session U2). As of day one, the conversion logic and the GUI were still mixed together in one file. Since that makes it impossible to write tests (you can’t check the logic without launching the GUI), I end up separating the core (logic) from the GUI (screen). Changing a design for the sake of “so we can write tests” was, for me, a first. Along the way, I also get into an idea called the “latin-1 fallback,” for implementing character-encoding detection using nothing but Python’s standard library.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems.
    Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/
    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.

  • The Day I Ported My System to a Different Project — The Moment an AI Fakes Understanding

    This article was originally written in Japanese and translated into English with AI assistance. Please note that some expressions may carry nuances from the original Japanese.

    🇯🇵 日本語版はこちら / Japanese version


    Series: Special Edition (Part 11)


    In SP08, I wrote about how my project knowledge grew too large, and Claude ended up talking about a completely different project. This time is the continuation of that story, and the theme is the trap that opens up the moment you try to carry a system that’s working well into a different project.

    Let me give away the conclusion first: “a system works well precisely because the explanation of why it works has been left out, and the part that’s left out exists only inside the heads of the people (and the AI) who are there. Carry it somewhere else, and exactly the omitted part disappears cleanly, leaving the AI to faithfully misread what remains.” That’s the gist of it.

    That’s the whole story. Before the main part, let me briefly explain two mechanisms that will come up repeatedly.


    Premise: A Mechanism That Has AI Write the Record of Each Session

    Every time a session ends, I have an AI write up the record of it (a journal). The mechanism has two layers: the ground floor is a generic template (items common to every project), and the second floor is a specialization layer (a single file collecting only the elements specific to that project). Combine the two and you get a prompt custom-built for that project.

    One more thing. The Chat side (why a given decision was made) and the Code side (what was actually done) each write their own journal separately, so I tie the two together with a matching number called a session_id. If they drift apart, you can’t cross-reference them later, so there was also a rule for which side assigns the number.

    For this article, all you need to know is three things: “it’s a two-layer structure,” “the two sides are tied together by a session_id,” and “there’s a numbering rule.”


    Now, on to the main story.


    How It Started: Digging Up a Stalled Development Idea

    One day, I dug up a development idea I’d started on in the past and left stalled partway through. Looking it over, it was further along than I’d remembered, and it seemed worth restarting.

    It happened to be right around the time the journaling mechanism for this blog’s project had settled down and was working quite well — a fairly mature setup, polished over dozens of sessions. So I thought:

    “Let me spin up the idea I’m restarting as a new project in Claude.ai too, and put the journaling workflow in place from the very start. If the mechanism works well on the blog side, it should work for a different piece of development too.”

    So I fed the journal-creation prompt I use on the blog side (the latest version at the time — I’ll later call this “the second edition”) into the new project.

    The environment at that point had the blog project running in the desktop Claude app and the new development project running in the browser version, side by side. Same Claude, but since the projects were different, they were running as completely independent, separate entities. This turns out to matter later.

    The result was more confusion than I’d imagined.


    What Happened: Five Missteps, Chained Together

    Right after starting the session in the new project, I fed the AI the “specialization-layer creation prompt” (the one for building the second floor of the two-layer structure). The AI’s response looked polite and sincere on the surface. But looking at the output, I froze.

    Misstep 1: The Specialization Layer Came Out as Two Files

    The AI created two files: “Specialization Layer_chat_(project name).md” and “Specialization Layer_code_(project name).md.” It’s supposed to be one file. The specialization layer is shared material referenced by both custom versions, and the design called for keeping it consolidated in one place.

    Why the split? Because the prompt said, “Please produce both a version for Claude.ai chat and a version for Claude Code.” What I meant was “since both will be used in a later step, please make material that both can reference” — but in Japanese, that line can also be read as “please produce two files.”

    I was writing from inside my own context, so I knew what I meant. The AI in the new project had none of that context at all.

    Misstep 2: It Asked for the Generic Template — Twice

    While building the specialization layer, the AI asked, “Could you show me the generic version of the template?” There was no need to see the generic version at this stage. Combining the two happens in the next step. The AI was trying to get ahead of itself and look at it before building the combined custom version — a sincere enough suggestion, but it didn’t mesh with the three-step structure I had in mind.

    Misstep 3: It Read a Neutral Explanation as “Pointing Out a Failure”

    When I explained, “At the step-1 stage, I won’t be handing over the generic version,” the AI started apologizing: “I’m sorry, I misunderstood.” But I wasn’t pointing out a failure — I was neutrally explaining an operating rule. AIs have a near-reflexive tendency to process any explanation from the user as “my own mistake.” It’s a sign of politeness, but excessive self-blame breeds the next misunderstanding.

    Misstep 4: It Couldn’t See the Three-Part Structure

    To begin with, the journal-creation prompt I was operating had a three-part structure — Part 1 builds the specialization layer, Part 2 builds the Chat custom version, Part 3 builds the Code custom version — and within the blog’s project, these three parts were bundled together into “a single notepad.” I meant to cut out and feed in only “Part 1,” but from the AI’s point of view, what landed on it was “a fragment with no visible whole.”

    The AI has no choice but to guess “what is this work for” and “how far does the scope go” from nothing but the text in front of it. Since I hadn’t conveyed the three-part structure, it assembled a different interpretation instead: “split it in two, get shown the generic version too, and go all the way through to combining them.”

    Misstep 5: The Numbering Rule Never Got Through

    The session_id needs to match exactly between the Chat side and the Code side. The numbering rule was well established on the blog side, but it had never been conveyed to the AI in the new project at all — I hadn’t written it down, taking it for granted, and I hadn’t spelled it out in the prompt either. As a result, the AI started guessing at its own numbering rule, and its behavior drifted subtly out of step with how things ran on the blog side.


    All Five Missteps Traced Back to the Same Root

    The five malfunctions look like separate stories, but sorted out, they all arose from the same underlying structure.

    Root Cause: A New Project Shares No Context

    Claude.ai’s project feature is completely independent, project by project. I think that’s the right design. If chat history from Project A leaked into Project B, that would be a serious information-management problem.

    But there’s a side effect. The implicit context built up over dozens of sessions carries over to a new project not at all. “The specialization layer is one file,” “the three-part structure,” “the numbering rule” — every one of these was an implicit premise that had settled into place only after repeated back-and-forth. The moment they’re fed into a new project, they all vanish. The new project knows nothing of the context the blog project had accumulated. Information not written into the prompt is treated exactly as if it doesn’t exist.

    Whatever Isn’t Written Down, All Disappears

    To run a prompt that worked well in one project inside a different one, every implicit premise had to be written explicitly into the prompt itself: what it’s for (its operational purpose), what to build, what not to build (out of scope), where it sits within the overall structure, in what order it runs, how metadata like the session_id gets numbered, what other related prompts exist — information that never needed spelling out in its original home now has to be fully put into words, or it doesn’t get through at all, in the new project.

    What started this all off was porting the system into a development project in a different domain from the blog. But it wasn’t the difference in domain that actually mattered. Whatever a newly spun-up project happens to be, it simply doesn’t carry the context I’d built up.

    Which is to say, the five missteps this time were a structural problem, unrelated to the content of the project. The moment you launch a new project, the same trap sits there waiting, jaws open.

    The Cost of Course-Correcting Is on a Whole Different Order

    And one more thing. Once a misunderstanding sets in, correcting it takes an enormous amount of additional prompting. Since all five were happening at once, even when I pointed out individually, “that’s not it,” or “here’s what I want instead,” the AI would respond politely and then trip into a different misunderstanding somewhere else. The chain wouldn’t stop.

    In the end, I took the long way around. That’s the repair process I’ll write about next. In short: getting things onto the right track within the first few exchanges is cheaper by an order of magnitude.


    The Repair: Revisions From the First to the Third Edition

    Here, let me lay out the revision history of the journal-creation prompt.

    First and Second Editions: Both Still Assumed the Blog’s Context

    The first edition was the version made at the very start. The three-part structure already existed, but the explanation of each part, the operating flow, and explicit statements of what not to do were all unrefined, and it carried a lot of unspoken understanding.

    In the second edition, I made a first round of fixes in the main session (desktop Claude). The three-part structure got clearer, and the metadata block got more organized. But even at this stage, “being fed into a different project on its own” still wasn’t something the design accounted for. This is the version I fed into the new development project, and that’s what set off the chain of five missteps.

    Having the One Who Tripped Write a Retrospective

    I had the Claude in the new project look back over its own behavior in chronological order. It produced a report: “Here’s where I misunderstood, and here’s what I infer the original intent actually was.” The party that had tripped put its own pattern into words. It wasn’t an outside evaluation — it was self-analysis by the party involved.

    The Third Edition: Fixed on the Managing Side

    I brought that report over to the blog’s main session (desktop Claude) and worked out a revision plan there. What mattered was that the one doing the fixing wasn’t “the party that had tripped” but “the one managing the journaling mechanism.” I judged that designing an improvement is properly the job of whoever can see the whole picture in an integrated way.

    The third edition changed the design philosophy itself, rewritten around the premise of “working without misunderstanding even when fed in on its own,” rather than “working within the blog’s own setting.” Four changes went in.

    Improvement 1: A “Four-Block Structure” at the Start of Each Part

    I designed each part to always open with the following four blocks:

    1. Why this work is being done (the operational purpose, this part’s position)
    2. What the AI does in this part (inside the scope)
    3. What the AI does not do in this part (outside the scope, the boundary with other parts)
    4. The expected operating flow (where this sits within the whole)

    These four blocks are everything implicit, put fully into words. What proved especially effective was “what not to do.” Spelling out “the specialization layer is to be created as a single file only” structurally prevents Misstep 1, and writing “displaying or quoting the generic prompt itself is out of scope” prevents Misstep 2 as well.

    Improvement 2: Splitting the Three Parts Into Separate Files

    Keeping the three parts bundled in one notepad was convenient for running things on the blog side, but it becomes a liability when fed into a different project. Feeding in the whole thing increases confusion, and cutting out only Part 1 leaves the context invisible, which increases misunderstanding in the other direction.

    So I split the three parts into three independent files. Each file is self-contained enough to be fed in on its own, with the four-block structure above placed at the top. At launch time, you feed in Part 1 first, then Part 2 when it’s done, then Part 3. The order became visible.

    Improvement 3: Adding “Three-Way Judgment Criteria” to the Sync Metadata

    The specialization layer holds a list of project-specific fields written into the journal. In the third edition, I had these broken down into three categories — “Chat-side only,” written only into the Chat journal; “Code-side only,” written only into the Code journal; and “shared,” written with the same value into both — and asked for example criteria to be given for each. This makes the sorting mechanical, leaving no room for judgment calls.

    Improvement 4: Spelling Out the Numbering Rule as a Table

    I placed a numbering-rule table (the same table shown under “which side assigns the number for which session type”) at the top of each part. This lets the AI in a new project immediately judge “what type of session am I in right now” and “whose turn is it to assign the number.” Operational knowledge established over dozens of sessions had been compressed into a single table.

    Verification: Showing the Fixed Version to the One Who Had Tripped

    Once the third edition was ready, I had the Claude in the new project — the one that had experienced the missteps — run the final verification. “Here are the five missteps you ran into the other day. Please read this third revision and evaluate whether each one is structurally prevented.” I think it mattered that this was shown to the party involved, not to some newly spun-up AI. The results were as follows:

    • Misstep 1 (splitting into two files): fully prevented (spelled out under “what not to do”)
    • Misstep 2 (asking for the generic template): fully prevented (same as above)
    • Misstep 3 (misreading a neutral explanation): partially addressed (fully preventing this through the prompt alone is difficult)
    • Misstep 4 (the three-part structure being invisible): fully prevented (each part is self-contained, with the operating flow diagrammed)
    • Misstep 5 (the numbering rule): fully prevented (the numbering-rule table is now in place)

    Four out of five fully prevented, one partially addressed. As a practical landing point, I didn’t think that was bad. The remaining Misstep 3 is less something to fix through the prompt and more something to absorb through how the human side responds — adding a line like “this isn’t pointing out a failure, it’s a neutral explanation.”

    Once confirmed, I finalized the third edition as the official version and placed it in SRW’s shared-assets repository. From now on, this is what I’ll feed into any new project I launch.


    Lessons — What Isn’t Written in the Prompt Doesn’t Exist

    I drew three lessons from this experience.

    Lesson 1: Implicit Context Doesn’t Exist in a New Project

    The “unspoken rules” and “premises that go without saying,” settled into place after dozens of conversations, don’t exist for the AI in a new project. When carrying a mechanism somewhere else, writing every implicit premise explicitly into the prompt becomes mandatory. This isn’t a matter of “writing carefully” — it means setting the design goal itself at “working without misunderstanding even when fed in on its own.”

    Lesson 2: The Power of Writing “What Not to Do”

    What proved surprisingly effective was writing down “what not to do.” If you write only “what to do,” the AI fills in the gaps with its own interpretation. Given “build the specialization layer,” it will, with the best of intentions, expand its own judgment into “split it,” “look at the generic version too,” “go all the way through to combining them.” A sincere move, but it drifts from the intent.

    Spell out “what not to do,” and you can deliberately narrow the room for the AI’s own judgment. This isn’t a restriction — it’s the prevention of misunderstanding.

    Lesson 3: Have the Party That Tripped Do the Review

    Once you’ve made an improvement plan, have it reviewed not by a newly spun-up AI but by the AI that experienced the missteps. A new AI can judge whether a document reads as well-organized, but it can’t judge whether it actually addresses its own pattern of tripping. There are blind spots only the party involved can see.

    That said, I felt the one making the improvement plan should be the manager, not the party involved. A design that resolves things in an integrated way can only be done by whoever is looking at the whole picture. “The party involved writes a report → the manager makes the fix → the party involved reviews it” — this three-stage process turned out to produce the most precise improvement.

    I think this applies to human organizations too. Rather than sidelining the person who failed, have exactly the person who failed do the final review.


    Summary

    This misstep unfolded in the following structure:

    1. Origin: I tried to port a system that was working well into a new project
    2. Blind spot: implicit context doesn’t carry over to a new project (a side effect of the independence of the project feature)
    3. Result: five missteps occurred at the same time, in parallel
    4. Repair cost: once a misunderstanding sets in, it takes multiple sessions to undo

    The repair proceeded as follows: the first edition (the original version) → the second edition (rewritten, but still assuming the original context) → put into practice in a different project, where the five missteps occurred → having the party involved write a retrospective → the third edition (fixed on the managing side, shifting the design philosophy to “works when fed in on its own”) → reviewed by the party involved → finalized as the official version.


    Collaborating with AI tends to get discussed in terms of how good or bad a given prompt is. But what actually breaks down in practice, I’ve come to feel, is most often the moment a prompt gets carried into a different context. The mechanism running well on the blog side was optimized for the blog’s own context. The moment it moved to a different project, the implicit premises hidden inside that optimization all surfaced at once.

    If you sense “this mechanism could work elsewhere too,” the first thing to doubt is “is it really written in a form that works elsewhere?” If it only runs on the assumption of its original context, it isn’t a generic mechanism — it’s a mechanism built for that one place.

    Making a mechanism generic also means putting everything implicit into words. Tedious, unglamorous work — and it pays off. I have a feeling that most of the operational know-how of working with AI accumulates in exactly this area.


    About Soul Resonant Works

    Soul Resonant Works is a solo venture developing seven local AI systems. Starting from zero programming experience, the development is progressing through collaboration with AI.

    🌐 Soul Resonant Works:
    → https://sr-works.net/en/index.html

    📝 This blog publishes the entire development process as a serialized journal.


    CubePlot (free version available)

    CubePlot is the first product from Soul Resonant Works — it turns a CSV into a 3D scatter plot you can rotate and zoom. No install, no sign-up: it’s a single HTML file you open in your browser, and it works offline. CubePlot itself does not send the data you load outside your machine — external network traffic is blocked at the browser level (CSP). Start with the free version.

    ▶ Product page: https://sr-works.net/en/cubeplot/

    ▶ Get it (commercial license, USD $39 + tax where applicable): https://soulworks8.gumroad.com/l/pzcij


    If you found this article useful, please share it.